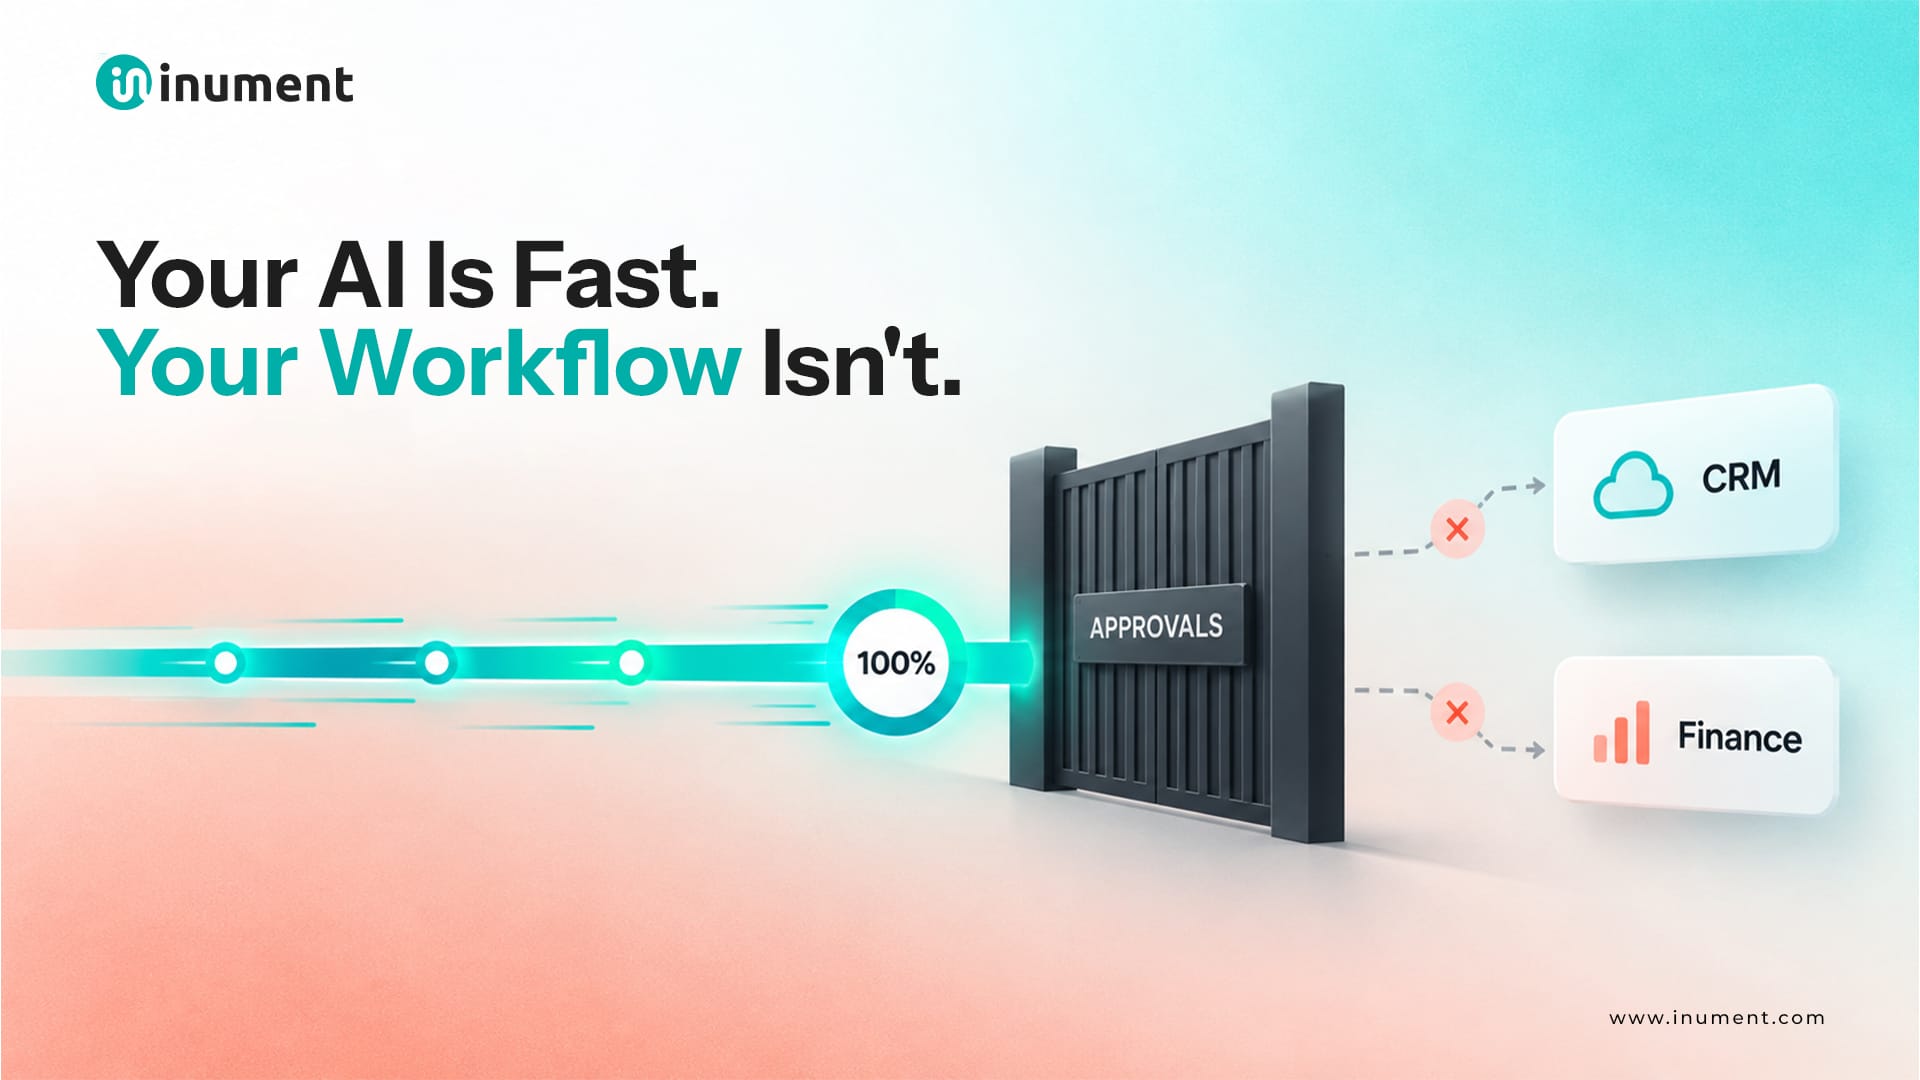
Your AI Is Faster. Why Is Your Business Still Waiting?

Your AI Is Faster. Why Is Your Business Still Waiting?

13 October 2026

|

IconInument

Icon Icon Icon

Imagine an AI agent reviewing a customer refund request in seconds. It checks the order history, verifies the details and recommends a resolution.

Yet the customer waits another two days.

The problem? The finance system is disconnected, approvals still happen through email, and employees must manually update customer records.

The AI completed its task. The business process remained slow.

This is an overlooked challenge in generative AI integration for enterprise operations. Companies invest in intelligent tools expecting faster results, but often discover that the processes surrounding those tools haven’t changed.

A faster AI system doesn’t automatically create a more efficient business.

AI Productivity Is Growing. Business Transformation Is Harder.

In October 2026, McKinsey published AI Is Changing Work. Now It Has to Change the Organization, highlighting an important difference between AI adoption and organizational transformation.

Its research found that nearly 75% of AI high performers substantially redesign their workflows, compared with approximately 25% of other organizations.

Although these findings show an association rather than direct causation, they point to an important pattern.

Organizations achieving greater AI impact are more likely to rethink how work happens, rather than simply introduce new tools.

Consider a customer support department where AI generates responses instantly, but employees still switch between multiple applications to resolve requests.

Technology improves one activity. The wider process remains inefficient.

For business leaders, the real question becomes: Are we improving individual tasks, or improving how the entire operation works?

The Hidden Problem: Disconnected Business Workflows

Most enterprises operate across multiple applications, departments, and approval processes.

Customer information lives in a CRM. Financial transactions happen in an ERP. Internal requests move through separate platforms.

These systems may work well individually while creating delays whenever information needs to move between them.

Introducing AI can accelerate certain tasks without removing those delays.

Sometimes manual approvals are necessary for security or accountability. Other times, they exist because systems were never properly integrated.

The challenge is determining which steps need human judgment, which require better integration, and which can safely be automated.

Without that understanding, businesses risk automating the same inefficiencies they intended to eliminate.

What Generative AI Integration for Enterprise Actually Requires

Successful enterprise AI implementation involves more than connecting an AI model to existing software.

Three engineering considerations are particularly important.

1. Reliable Data and System Integration

AI must access accurate information from authorized business systems.

This requires secure APIs, dependable data pipelines, and clear access permissions.

An AI agent may need to retrieve payment information, for example, without having unrestricted permission to initiate transactions.

The architecture must distinguish between accessing information and executing business actions.

2. Safe Automation and Failure Recovery

Imagine an AI-supported refund workflow where the payment succeeds but the CRM update fails.

If the system automatically repeats the entire process, the customer could receive a duplicate refund.

Reliable engineering addresses these risks through transaction tracking, controlled retries, idempotency safeguards, and recovery mechanisms.

These decisions rarely appear in AI demonstrations, yet they determine whether automated workflows can operate safely in production.

3. Monitoring and Accountability

When an AI-supported process produces an unexpected result, businesses need to understand what happened.

Which information influenced the response? What action was attempted? Was human approval required?

Continuous evaluation, system monitoring, and appropriate audit records make AI operations easier to investigate and improve.

Production-ready AI depends on the reliability of the entire system, not just the model behind it.

Better Engineering Must Support Better Business Processes

Even technically reliable AI cannot fix every operational problem.

If an organization has five unnecessary approval stages, developing an AI agent to navigate them may increase speed without removing the underlying complexity.

Business leaders must first decide how the process should work.

Engineering teams can then implement the required integrations, automation, safeguards, and supporting infrastructure.

Success also needs to be measured beyond AI response times.

End-to-end resolution time, operational errors, manual intervention, and cost per completed process provide a clearer picture of business impact.

The objective should be to improve the outcome, not simply increase the number of automated activities.

How Inument Approaches AI Transformation

At Inument, we focus on the engineering that connects AI capabilities with practical business applications.

Our expertise includes AI and machine learning development, workflow automation, backend engineering, API integration, and cloud infrastructure.

Our published work in AI-powered e-commerce search and discovery describes Adaptive Transformer Search technology, an example of applying AI within a digital product rather than treating it as a standalone tool.

For enterprise applications, the right approach depends on existing infrastructure, operational requirements, and business objectives.

Sometimes an AI agent is appropriate. In other cases, better system integration or conventional automation may deliver greater value.

The priority is choosing an engineering solution that addresses the actual business problem.

The Real Opportunity Goes Beyond Faster AI

AI can help employees complete tasks faster, but meaningful business transformation happens when entire workflows become more efficient.

That requires connected systems, thoughtful process redesign, reliable engineering, and clear accountability.

For businesses investing in AI, the real measure of success is how effectively technology improves operations and delivers measurable value.

The question is no longer how fast AI can work, but how much better the business can perform because of it.

About the Author

Safkat Nirjash

Safkat Nirjash

Want to Build Your Dream Tech Team? Hire Now!

Your Project Doesn’t Need Agile. It Needs the Right Delivery Model

Your Project Doesn’t Need Agile. It Needs the Right Delivery Model

2 October 2026

|

IconInument

Icon Icon Icon

Many software teams are not struggling because they lack Agile practices.

They struggle because they are using the wrong delivery model for the problem they are trying to solve.

A startup launching a new product, a bank modernizing legacy systems, and an enterprise implementing AI-powered workflows all have different challenges. They require different levels of flexibility, control, speed, and engineering support.

Yet many companies still start with the same question:

Should we use Agile or Waterfall?

The better question is:

What delivery model gives this project the highest chance of success?

In 2026, successful software delivery is not about following one methodology. It is about creating a delivery approach that matches the business goal, technical complexity, team structure, and operational needs.

Methodology Is Not the Strategy

Agile transformed software development by improving collaboration, feedback cycles, and adaptability.

But many companies focus too much on Agile processes:

  • Sprint meetings
  • Story points
  • Backlogs
  • Daily standups

while ignoring the real challenges:

  • unclear ownership
  • changing business priorities
  • poor communication
  • technical debt
  • slow deployment processes
  • disconnected teams

A team can follow Agile perfectly and still fail if the delivery system around it is broken.

The goal is not to follow a methodology.

The goal is to build a system that helps teams deliver better software.

The Project Should Define the Approach

Different projects require different priorities.

A new product exploring market demand needs speed and continuous feedback.

A regulated financial platform needs security, stability, and strong governance.

A large enterprise modernization project needs careful planning, migration strategy, and risk control.

There is no universal delivery model.

The right approach depends on what the business needs most.

Why Good Teams Still Miss Delivery Goals

Many software delays are not caused by developers.

They come from problems around the engineering process:

  • unclear product direction
  • slow decision-making
  • disconnected tools
  • weak testing processes
  • inefficient deployment workflows
  • lack of technical alignment

This is why modern software development requires strong product engineering.

Product engineering connects business goals, customer needs, and technical execution to create software that delivers measurable value.

Software Delivery in the AI Era

Many companies are now introducing AI tools, AI agents, and AI workflow automation into their operations.

But adding an AI solution does not automatically create transformation.

The real challenge is integrating AI into existing workflows.

A successful AI implementation requires:

  • reliable data access
  • system integration
  • clear ownership
  • business rules
  • human review
  • performance measurement

An AI agent without the right workflow becomes another disconnected tool.

The value comes from building the right operating model around the technology.

Building the Right Delivery Model for Modern Businesses

Modern software projects require collaboration between:

  • product teams
  • software engineers
  • AI engineers
  • data teams
  • operations leaders
  • business stakeholders

A strong delivery model creates alignment between these groups.

It answers important questions:

Who owns the outcome?

How are decisions made?

How quickly can teams test ideas?

How does the system scale?

How is quality maintained?

These questions become even more important when companies move from AI experiments to production-ready AI systems.

Engineering Capability Still Matters

Technology success depends on more than tools.

It requires:

  • software architecture
  • cloud infrastructure
  • secure integrations
  • data engineering
  • Testing
  • Monitoring
  • continuous improvement

For companies that need additional expertise, embedded engineering teams and tech staff augmentation can help accelerate delivery without creating unnecessary long-term complexity.

The goal is not simply adding more developers.

The goal is adding the right engineering capability at the right time.

Inument’s Perspective

At Inument, we believe successful software delivery starts with understanding the business problem first.

Companies need technology that improves operations, supports growth, and creates measurable outcomes.

Through AI transformation, software engineering, workflow automation, system integration, cloud engineering, and embedded engineering teams, Inument helps organizations move from ideas to production-ready systems.

The right technology creates value only when the right execution model supports it.

Choose the Model Before the Methodology

The future of software development is not about choosing Agile, Waterfall, or any single framework.

It is about designing the right delivery system for the right business challenge.

The companies that succeed will be the ones that align people, processes, technology, and engineering teams around a shared goal.

Before choosing a methodology, ask:

Does our delivery model actually support the outcome we want to achieve?

Because great software is not created by following a process.

It is created by choosing the right process for the right problem.

About the Author

Safkat Nirjash

Safkat Nirjash

Want to Build Your Dream Tech Team? Hire Now!

Cloud Didn’t Fix Your Architecture. AI Just Exposed It

Cloud Didn’t Fix Your Architecture. AI Just Exposed It

24 September 2026

|

IconInument

Icon Icon Icon

AI didn’t create the need for scalable infrastructure. It exposed which systems were never built for scale in the first place.

For years, enterprises treated cloud migration as the finish line and AI as a series of isolated experiments. That period is over. The bill for undisciplined experimentation has arrived, and it’s landing in two places: prototypes that work in a demo and collapse in production, and cloud environments quietly draining operating budgets.

The lesson underneath all of it is simple. Moving a workload to the cloud doesn’t make it scalable. Re-architecting it does. Real scale is what happens when infrastructure, AI workloads, data flow, cost control, compliance, and developer velocity finally operate as one connected system instead of six competing ones.

The diagnosis: why pilots die in production

Enterprise AI projects are failing to deliver their promised returns, and the cause is almost never the model. It’s the engineering around it. AI performs beautifully in a controlled development environment, then meets the compute, storage, and latency demands of real traffic and falls over.

The money involved makes this more than an engineering footnote. Synergy Research put enterprise cloud infrastructure spending at $419 billion in 2025, with generative AI as the primary driver. Gartner forecasts worldwide AI spending will reach $2.52 trillion in 2026. Capital is pouring into modern systems at a scale the industry has never seen.

But capital without structural precision buys expensive friction, nothing more. Companies aren’t re-architecting because the cloud is fashionable. They’re doing it because business speed now depends directly on infrastructure maturity, and most infrastructure isn’t mature.

The waste is an architecture choice, not an accident

Here’s the uncomfortable proof. Flexera’s 2026 State of the Cloud Report found that 29% of IaaS and PaaS cloud spend is now wasted, the first increase after five straight years of decline.

What makes that number striking is everything sitting next to it. In the same report, 81% of enterprises use generative AI, 71% run hybrid cloud, 63% have dedicated FinOps teams, and 71% operate a Cloud Center of Excellence. The governance structures are in place. The waste went up anyway.

That’s the tell. When maturity practices exist and money still leaks, the problem isn’t discipline. It’s the foundation those practices are sitting on. Teams are treating symptoms while the root cause of poorly structured architecture keeps generating new ones.

AI tools don’t fix this. They amplify whatever is already there. Google found roughly 90% of software professionals now use AI tools, but the outcome splits along one line: well-architected teams use them to ship faster, while fragmented teams use them to produce low-quality code faster, exposing the cracks they already had.

Match the architecture to the workload, not the trend

Consider Prime Video’s well-known correction. Their team re-architected a video-quality monitoring service, moving from a heavily distributed, serverless design back to a focused, consolidated one on Amazon ECS and EC2. The result was a cost reduction of over 90% and higher scaling capacity at the same time.

The lesson isn’t “monoliths beat microservices.” That’s the wrong takeaway, and chasing it just trades one mismatch for another. The real lesson is that architecture has to match the actual behaviour of the workload, how data moves, where the bottlenecks are, and what it costs to run. Distributed isn’t automatically better. Neither is consolidated. Fit is what matters, and fit is a decision most migrations never actually make.

The harder limits: compute, power, and data lineage

Beyond software design, the physical limits of infrastructure are now setting the ceiling on how fast a business can move. McKinsey estimates data centres will require around $6.7 trillion in global capital spending by 2030 to meet demand, with roughly $5.2 trillion of that tied specifically to AI workloads. Global data-centre capacity is projected to triple by 2030, most of it consumed by AI.

When that pressure hits systems that were never optimised, the failures are specific and expensive. Machine-learning models saturate standard storage during checkpointing and stall entire GPU clusters burning compute without completing a single training step. Autonomous AI agents deployed without decision transparency run straight into emerging regulation, exposing the business to real legal liability.

And the value gap is stark. McKinsey estimates disciplined cloud adoption could unlock around $3 trillion in value across the world’s largest companies by 2030 yet only about 10% of cloud transformations capture their full intended value. The other 90% stay trapped by the legacy structure they never re-architected.

The treatment: what re-architecting actually looks like

The companies getting this right treat infrastructure as a product, not a one-time migration.

Capital One is one of the clearest examples. They exited eight on-premises data centres and moved entirely to AWS but not as a lift-and-shift. They rebuilt roughly 80% of about 2,000 applications from the ground up on modern stacks. The payoff was operational: disaster-recovery testing times dropped 70%, critical incident resolution improved by 50%, and developer environment provisioning went from three months to minutes. They became a technology company that happens to do banking.

Shopify turned the same discipline into revenue. By replatforming onto a distributed, cloud-native engine, they carried the extreme concurrency of a peak Black Friday–Cyber Monday event without an outage sustaining billions in merchant sales and millions of requests per second at peak. At that scale, reliability isn’t a technical nicety. It’s the revenue.

A practical way to get there

Moving from fragile to production-ready doesn’t happen in one leap. It works as a sequence, and the order matters.

Start with governance, not compute. Before scaling a single AI workload, map every data source feeding your production models and put verifiable data lineage in place. Any system that can’t show where its data came from should be isolated before it becomes a compliance problem, not after.

Then fix the structure. Audit how your services actually communicate. Find the distributed components bleeding time and cost to data-transfer latency and consolidate them where consolidation fits. Build a central control plane so workloads can shift across zones based on availability and cost instead of being pinned in place.

Then make discipline permanent. Put continuous monitoring across the infrastructure layer aimed squarely at that 29% waste. Trigger scaling on real signals like data throughput, not just CPU. And treat the whole system as a product you keep improving, not a project you finished.

The mandate

The organisations pulling ahead aren’t the ones that spent the most on AI models or cloud credits. They’re the ones that built systems where reliability, cost, and performance behave predictably at scale because that predictability was engineered in, not hoped for.

That’s the shift underway right now: from buying AI dreams to demanding systems that actually run. Your infrastructure is either accelerating the business or quietly holding it back, and cloud spend alone won’t tell you which. The architecture underneath will.

This is the work Inument focuses on the senior engineering judgment to move an enterprise from fragile, expensive infrastructure to a system that scales on purpose. Not another migration. A foundation that stops leaking value every time you try to grow.

Eliminate the structural fragility. Build something that scales.

About the Author

Safkat Nirjash

Safkat Nirjash

Want to Build Your Dream Tech Team? Hire Now!

AI Reliability Debt: The Hidden Cost of Production AI Systems

AI Reliability Debt: The Hidden Cost of Production AI Systems

14 September 2026

|

IconInument

Icon Icon Icon

Your AI didn’t crash. It just quietly stopped being trustworthy and no one noticed for weeks.

That’s how this failure works. It doesn’t announce itself.

A model performs well in a demo. Leadership is impressive. It ships. For a while, it looked like a win.

Then real users arrive, and the cracks open in places nobody was watching.

The AI gets incomplete context from an upstream system. A connected API times out, and the workflow degrades instead of stopping. Someone tweaks a prompt to fix one case and silently breaks another. Output quality drifts down so slowly that no single person catches it. An agent takes an action it shouldn’t have and when the team digs in, they can’t reproduce why.

The model is technically running. But the system around it is getting harder to trust, debug, update, and scale.

That slow build-up of weakness is AI reliability debt.

A familiar problem in an unfamiliar place

Engineers already know its older cousin. Technical debt, the cost of shipping quick, imperfect code and paying interest later is a normal part of building software.

AI reliability debt works the same way. It just hides somewhere new.

It rarely comes from the model. It comes from everything the model depends on, and everything that depends on the model:

  • No systematic way to evaluate AI output
  • Weak observability, so failures can’t be reconstructed
  • Poor context and data architecture feeding the model
  • Too much agent autonomy, too few guardrails
  • No fallback when a step fails
  • Unreliable third-party integrations
  • Prompt and model changes shipped without regression testing
  • No human escalation path when the AI is unsure
  • No monitoring of output quality over time
  • No clear owner when an AI decision goes wrong

Each gap looks minor on its own. A missing test here, an unwatched output there.

Together, they decide whether the system holds up when it matters.

Why you don’t see it at launch

Here’s the trap: the debt is invisible on day one.

The demo works. The first users are happy. The dashboards look clean. The debt is already there, it just hasn’t come due.

It comes due at scale. Volume rises, and edge cases multiply. More workflows lean on the same model, and one small prompt change ripples further than anyone expected. The system runs long enough that quality drift shows up in business results, not error logs.

By the time it’s obvious, it’s expensive because it’s now wired into live operations.

A system can pass every launch test and still start accumulating this debt the moment it meets messy, real-world input.

Why this reaches past engineering

It’s tempting to call this an engineering problem. It isn’t. That’s the point.

An unreliable AI system doesn’t just make errors. It makes confident errors.

It can push a wrong recommendation into a real decision. It can frustrate customers with behaviour that changes day to day. It can create operational risk when an agent acts in a bad context and nobody catches it.

There’s a slower cost underneath. Every hour spent firefighting an opaque AI failure is an hour not spent building the next thing. Reliability debt raises maintenance cost, slows future AI work, and quietly erodes trust.

And once leadership stops trusting an AI initiative, more investment is almost impossible to justify however good the model is.

So the real question for a CEO or CTO isn’t “does our AI work?”

It’s “can we trust what it does when no one’s watching, and explain it when it’s wrong?”

From “works in a demo” to “trusted in production”

Closing that gap isn’t about a smarter model. It’s about engineering the system around it to behave under real conditions.

Evaluation that measures output quality continuously, not once. Observability detailed enough to reconstruct any decision. Data pipelines that deliver clean, complete context. Integrations that fail gracefully instead of silently. Guardrails that keep agent autonomy inside safe limits. A human escalation path for the calls the AI shouldn’t make alone. A clear owner when something breaks.

This is the work that turns a sharp prototype into a system a business can depend on. It’s also the easiest work to postpone because none of it shows up in a demo, and all of it shows up at scale.

Helping companies make that exact move from AI that works in a demo to AI that can be trusted in production is where much of Inument’s engineering sits: AI architecture, evaluation and observability, data and integration pipelines, cloud infrastructure, guardrails, and human-in-the-loop workflows.

The next edge in AI won’t come from the smartest model.

It’ll come from the most reliable system built around it.

And once leadership stops trusting an AI initiative, more investment is almost impossible to justify however good the model is.

So the real question for a CEO or CTO isn’t “does our AI work?”

It’s “can we trust what it does when no one’s watching, and explain it when it’s wrong?”

About the Author

Safkat Nirjash

Safkat Nirjash

Want to Build Your Dream Tech Team? Hire Now!

Quality Assurance Isn’t a Cost. It’s What Stands Between You and a Bad Reputation

Quality Assurance Isn’t a Cost. It’s What Stands Between You and a Bad Reputation

7 September 2026

|

IconInument

Icon Icon Icon
Quality Assurance Isn't a Cost

Your product will be judged by the one thing that goes wrong, not the hundred things that go right.

A customer doesn’t remember the checkout that worked ten times. They remember that once it failed, took their money, and showed no confirmation. That single moment is what they tell other people about. This is the real reason quality assurance matters, and it’s a much bigger idea than “finding bugs before release.”

Quality assurance is how a business makes sure that what it ships actually does what it promised, reliably, for real people, under real conditions. It isn’t a final checkpoint at the end of a project. Done well, it runs alongside the work from the first day, quietly deciding whether the thing you build is worth the money and time your customers give it.

What quality assurance actually is

Most people picture QA as someone clicking through an app looking for things that break. That’s part of it, but it undersells the point. QA is a disciplined process for confirming that a product meets a defined standard before your customers become the ones who discover it doesn’t. It’s less about catching mistakes and more about building in a way where mistakes have fewer places to hide.

The distinction matters because it changes when QA starts. If quality is only checked at the end, you’ve already paid to build the wrong thing. If it’s considered from the beginning, you avoid the problem instead of paying to fix it later.

Why it’s worth the investment

The value of QA becomes obvious the moment you count what poor quality actually costs.

It protects your reputation. Everything you release into the market becomes a public statement about your standards. Customers examine products closely, and if what they get falls short of what they expected, that gap becomes your reputation, no matter how good your marketing was.

It saves money, not spends it. A defect caught early is cheap to fix. The same defect caught in production, after it has frustrated users and reached support tickets, is far more expensive in engineering hours and causes lost trust and sometimes lost customers. Prevention is almost always cheaper than correction.

It protects the experience, not just the interface. Many quality problems don’t look like broken buttons. They look like a slow page, a confusing step or a workflow that technically works but wears the user down. QA that only checks whether features “function” misses this entirely. Good QA asks whether the product is actually usable, not just operational.

It compounds over time. A reliable product lets you charge with confidence, keep the customers you win, and grow without constantly firefighting. Quality isn’t a one-time expense. It’s a foundation the rest of the business stands on.

Is QA the same as testing?

This is a common mix-up. Testing is one activity inside QA, not a synonym for it. Testing checks whether a specific thing works. Quality assurance is the wider discipline that shapes how the whole product is built and delivered, the inputs as well as the outputs. They share a goal, a product the customer can trust, but QA is the system, and testing is one tool inside it.

Can your developers just handle QA themselves?

They can, but it’s rarely the strongest approach, and the reason is human, not technical.

When you build something, you naturally test it the way you expect it to be used. You check the paths you designed. What you tend to miss are the paths you never imagined, the odd input, the unexpected sequence and the edge case that only a fresh set of eyes goes looking for. A developer testing their own work carries an unconscious bias toward proving it works, not toward finding where it fails.

A dedicated QA perspective is different by design. It looks beyond the stated feature to everything that feature touches. It tests what should happen and, just as importantly, what shouldn’t. That independence is the whole point. It’s hard to objectively question something you just built.

Why this matters even more for startups and growing teams

For a small company, reputation is fragile and word travels fast. You don’t have the brand weight to absorb a bad first impression. Early customers are also your loudest reference, in both directions. Investing in quality early isn’t a luxury you earn later; it’s how you make sure the first version of your product earns the trust that everything else depends on. It also gives you an honest read on how your work is actually perceived, instead of guessing.

Where Inument fits

At Inument, quality isn’t a stage we bolt on before launch. It’s built into how our engineers work, because we embed directly in your team, follow your standards, and own the outcome, not just the code. That means the people building your product and the people safeguarding its quality are working from the same context, toward the same result: software your customers can rely on without thinking about it.

The best quality assurance is invisible. It’s the product that simply works, so well that no one notices the effort behind it. That’s the standard we build to.

Because in the end, quality decides whether what leaves your business is worth your customers’ money and time. And that, more than any feature, is what your business will be remembered for.

About the Author

Safkat Nirjash

Safkat Nirjash

Want to Build Your Dream Tech Team? Hire Now!

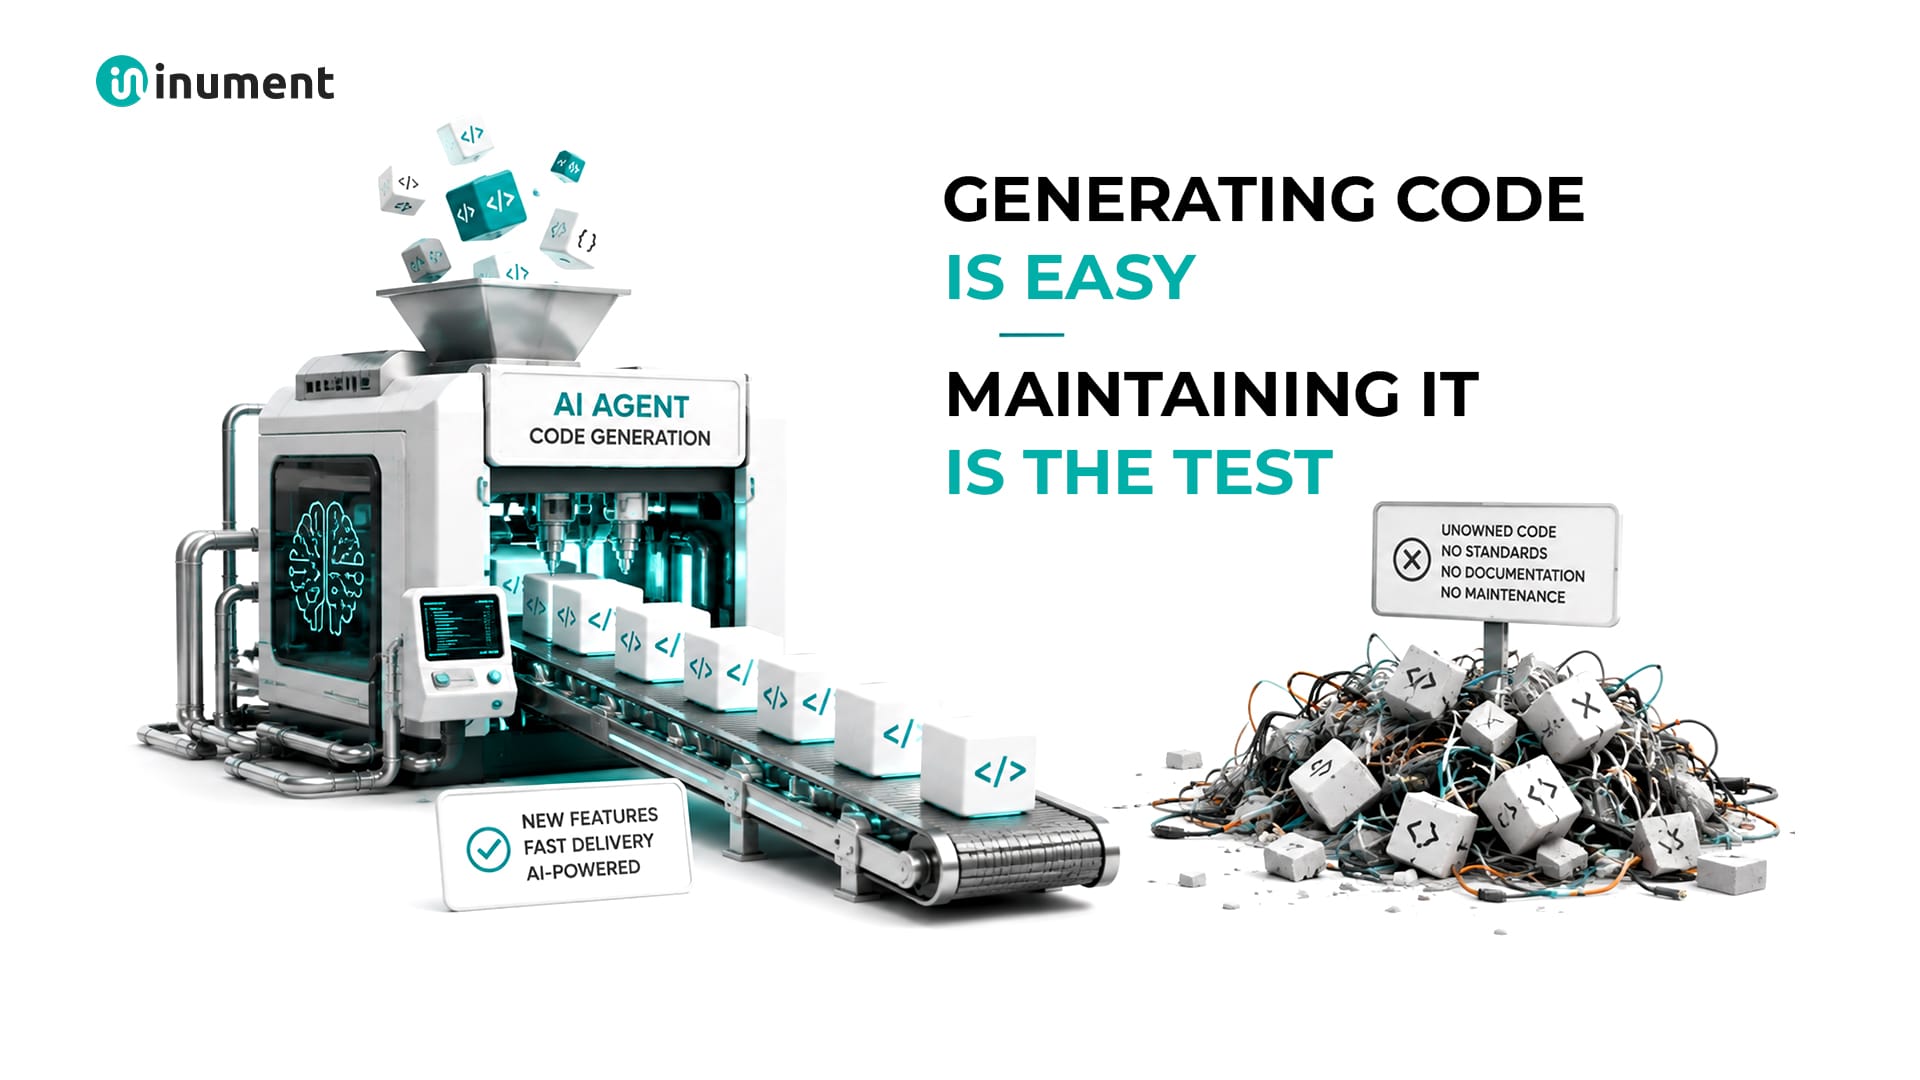
AI Can Generate Code. Can It Maintain the Codebase Six Months Later?

AI Can Generate Code. Can It Maintain the Codebase Six Months Later?

17 August 2026

|

IconInument

Icon Icon Icon

You have probably seen the demo by now. Someone types a prompt, an AI agent writes a working feature in minutes, and the room goes quiet in a good way. It feels like the whole cost of building software just dropped to zero.

Then six months pass.

The person who ran that demo has moved teams. The feature is now tangled into three other systems. A customer reports a bug, a developer opens the file, and nobody in the room can explain why the code was written the way it was. The AI that generated it is long gone from the conversation. What is left is a codebase that works until it doesn’t, and no clear owner when it breaks.

This is the real 2026 question for anyone running a business on software. Generating code was never the hard part. Living with that code, maintaining it, and trusting it inside daily operations is where most companies quietly struggle. And it exposes a truth that a lot of AI conversations skip over: an AI agent that produces output is not the same thing as a system your business can actually run.

The problem is not the AI. It is the missing operating model.

Most companies started their AI journey the same way. They gave a tool or an agent to a few smart people and waited for results. Some of those results were real. Plenty of them turned into a pile of half-finished projects that no one wanted to own.

The instinct is to blame the model. The model was not smart enough, the output needed too much cleanup, the tool was overhyped. Sometimes that is fair. But more often the model did its job and the organization simply had nowhere to put the output. No one redesigned the work around it.

That gap has a name. It is the operating model. And it is the difference between an AI experiment and an AI system that a business can depend on.

An AI operating model is not a piece of software. It is the structure that answers the practical questions every leader eventually asks. Who owns this AI system when it is running in production? Where does it sit in the actual workflow? Who reviews its decisions before they reach a customer? What happens when it gets something wrong? How does data move in and out of it? And how do we know, in numbers, whether it is helping?

If you cannot answer those questions, you do not have an AI system. You have a tool that happens to produce output. Code generation makes this painfully clear, because unowned code does not just sit there quietly. It rots.

Why AI agents fail even when the agent works fine

Think about what it actually takes for AI-generated code to survive past the demo.

It needs an owner. Not the person who wrote the prompt, but a team accountable for that code the way they would be accountable for anything else in production. Without ownership, no one refactors it, no one documents it, and no one notices when it starts causing problems downstream.

It needs to fit a workflow. AI can write a function, but your business does not run on functions. It runs on processes with reviews, approvals, handoffs, and standards. If the AI output skips all of that, it becomes a shortcut that creates work later instead of removing it.

It needs clean data and clear rules. An agent making decisions on messy inputs will produce confident, wrong answers. The same applies to generated code built against assumptions no one wrote down. When those assumptions change, the code breaks in ways that are hard to trace.

It needs integration. A feature that lives on its own island is easy to build and expensive to maintain. Real value shows up when AI output connects to the systems people already use, so the work flows instead of piling up in a corner.

And it needs human oversight built in on purpose, not bolted on after something goes wrong. Someone has to review the important calls, catch the errors, and decide when the AI should hand the decision back to a person.

Notice that none of these are model problems. They are operating model problems. The agent can be excellent and the outcome can still fall apart, simply because nothing was designed to catch the output and put it to work.

What a strong AI operating model actually includes

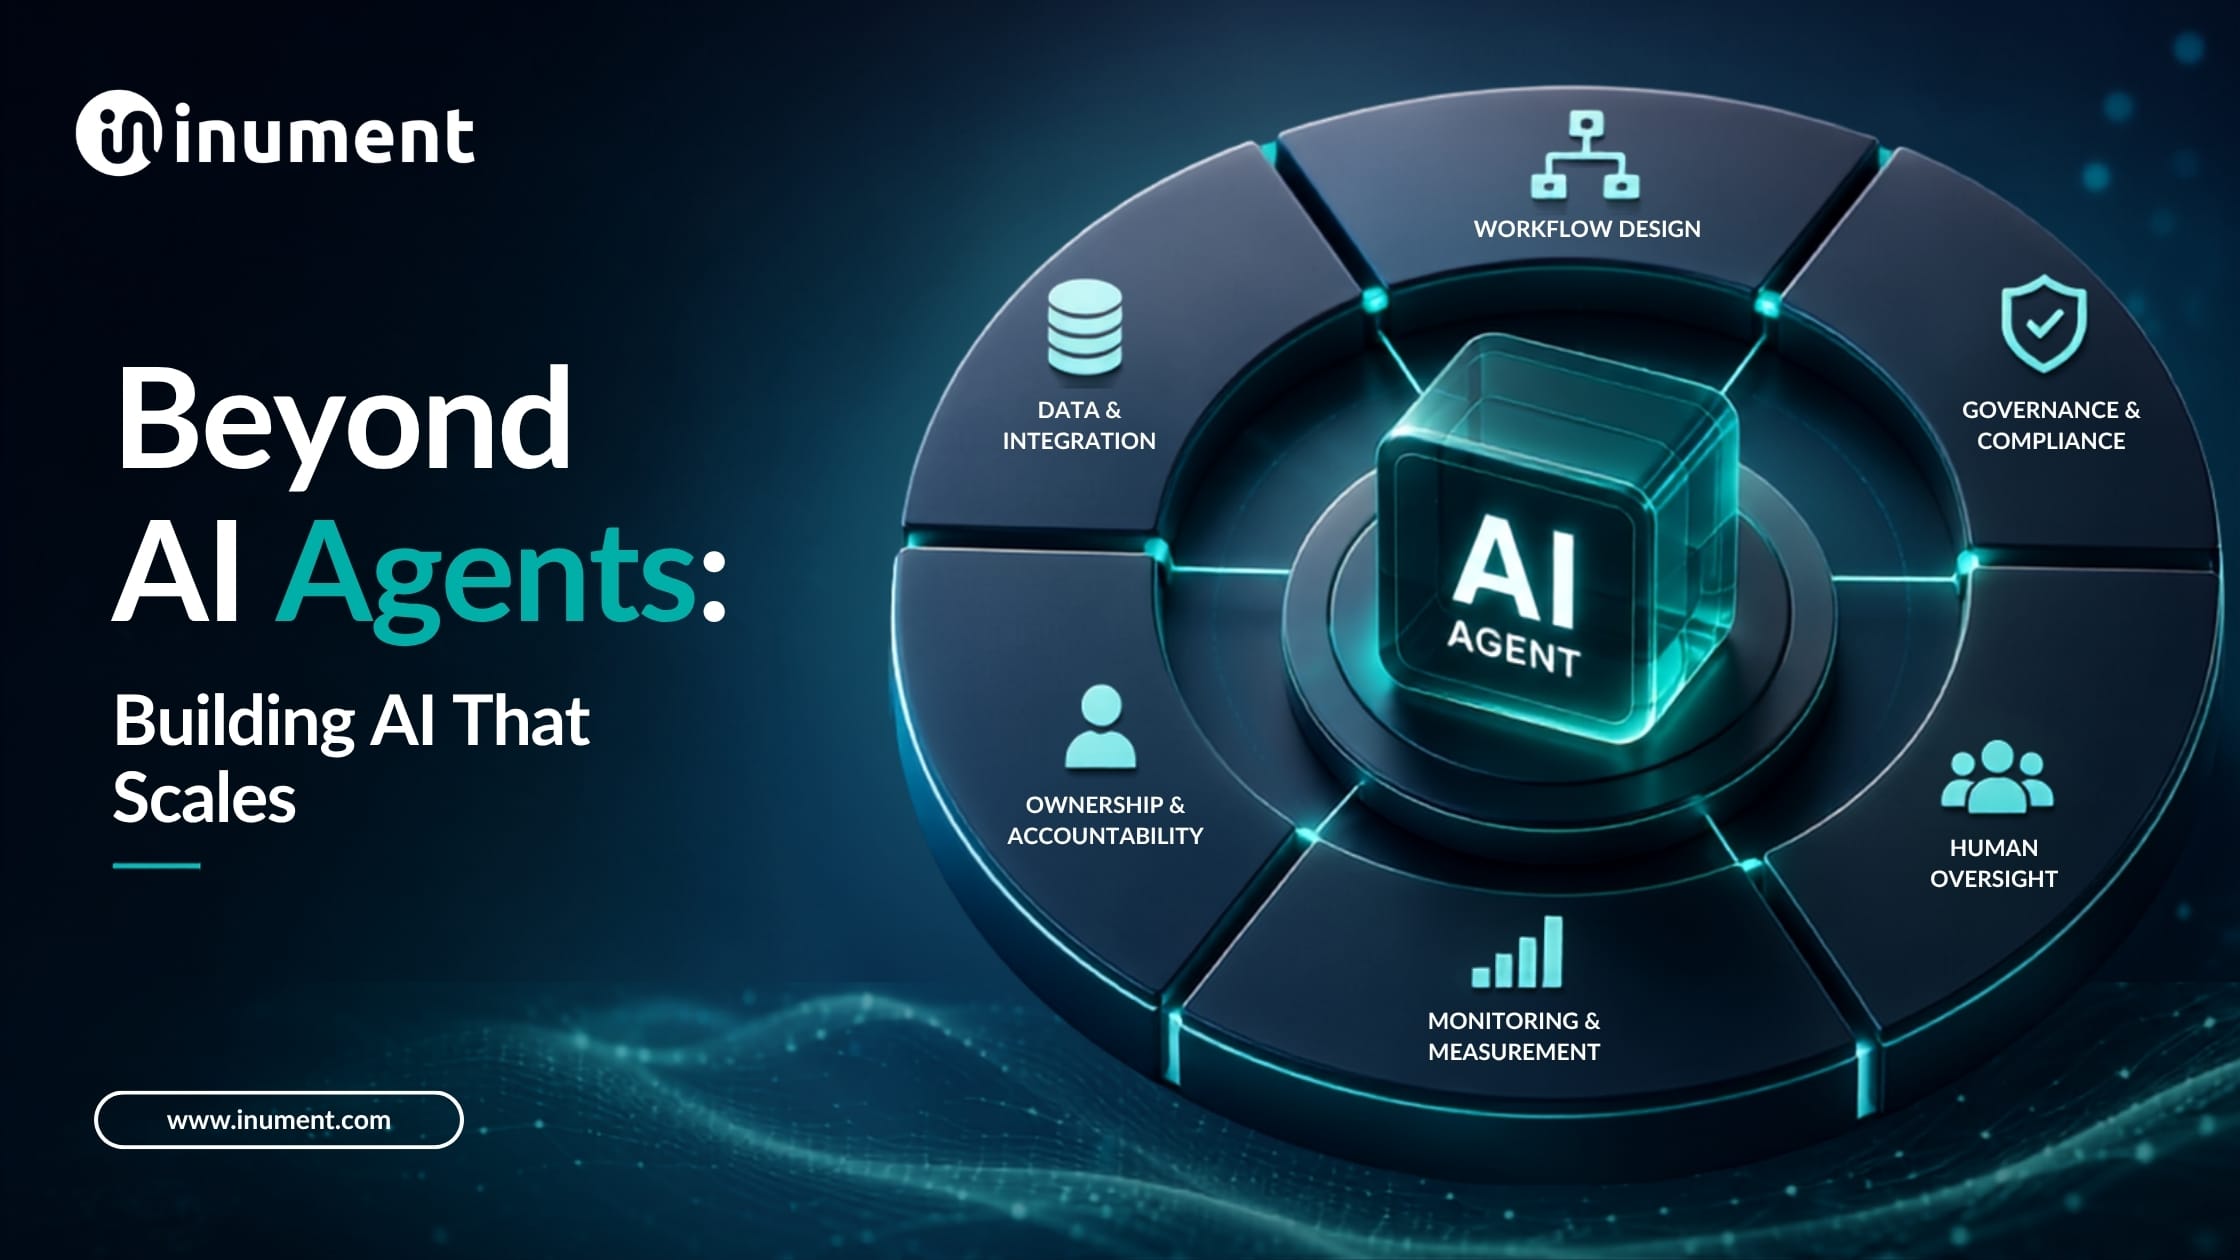
A working AI operating model is less about the AI and more about the system around it. A few parts show up in every version that holds up over time.

Clear ownership comes first. Every AI system in production needs a named team that is responsible for its behavior, its upkeep, and its results. Ownership is what keeps a smart feature from becoming an orphaned liability six months later.

Workflow design comes next. The AI has to be placed at a specific point in a real process, with a clear before and after. People need to know what the AI does, what it does not do, and where their own judgment takes over.

Then comes data readiness. The system needs reliable inputs, defined sources, and rules for what good data looks like. This is unglamorous work, and it is the difference between an agent you can trust and one you have to double-check constantly.

Human review has to be part of the design. That means deciding in advance which decisions get checked, who checks them, and how mistakes are handled when they slip through. Good oversight is not a lack of trust in the AI. It is what makes the AI safe to rely on.

Integration ties it together, connecting the AI into the tools and systems where work already happens, so nothing depends on one person remembering to move data by hand.

And finally, measurement. If you cannot see whether the AI is reducing effort, cutting errors, or moving a real business number, you cannot improve it and you cannot defend it. Success has to be defined before you build, not guessed at afterward.

From scattered agents to a system you can trust

Picture a mid-sized software company that leaned hard into AI code generation. Their developers used agents to ship features faster, and for a while it looked like a win. Velocity was up. Then the maintenance bills arrived.

Every developer prompted in their own style. Generated code landed in the repository with no shared standards and no consistent review. Six months in, half the team was afraid to touch code they did not write and could not fully explain. The AI had made the easy part faster and the hard part harder.

So they stopped adding tools and started building an operating model. AI-generated code became a first draft, not a finished product, and it entered the same review process as everything else. One team took ownership of the AI-assisted workflow, defined the standards the agents had to follow, and set the rules for what could ship automatically and what required a human sign-off. They connected the agents to their existing testing and deployment systems, so nothing bypassed the checks that already protected production. And they tracked simple, honest numbers: how much rework the code caused, how often it broke, how long fixes took.

The agents did not change. The result did. The same AI that had been creating quiet debt was now producing code the team could maintain, because there was finally a system built around it.

Where Inument fits

This is the work Inument focuses on. Building an AI agent is the part everyone can now do. Turning that agent into production-ready AI that a business can operate, maintain, and trust is where most companies get stuck, and it is exactly the gap we help close.

We help teams move from AI ideas and agent experiments to working AI systems through strong engineering, deliberate workflow design, real integration into existing tools, and scalable delivery teams that stay with the system past the demo. The goal is not more AI activity. The goal is AI transformation that holds up under the weight of daily operations, six months and six years later.

The real test

The companies that win with AI in 2026 will not be the ones that tried the most tools. They will be the ones that built reliable AI systems into how the business actually runs.

So it is worth asking a plain question about your own AI agents. Are they part of a system someone owns, reviews, and measures? Or are they producing output that works today and turns into a maintenance problem no one signed up for?

If you are not sure, that uncertainty is the answer. And it is a much better problem to solve now than to discover six months from now, when the code is already yours to keep.

About the Author

Safkat Nirjash

Safkat Nirjash

Want to Build Your Dream Tech Team? Hire Now!

Beyond AI Agents: How to Build the Operating Model That Makes AI Work at Scale

Beyond AI Agents: How to Build the Operating Model That Makes AI Work at Scale

27 July 2026

|

IconInument

Icon Icon Icon

AI agents are no longer the exciting experiment in the corner of the business.

By 2026, many companies have already tested them. Some have built internal copilots. Some have automated parts of customer support, sales, hiring, finance, or operations. Some have connected AI agents to documents, CRMs, analytics tools, and internal systems.

But a hard truth is becoming clear.

Building AI agents is not the same as making AI work at scale.

Many companies can now create an AI agent. Far fewer can turn that agent into a reliable part of the business. The difference is not only technical. It is operational.

An AI agent can answer questions, summarize documents, trigger workflows, and support decisions. But if the workflow around it is unclear, the agent becomes another disconnected tool. People may try it once, lose trust, and return to the old way of working.

That is why the next stage of AI transformation is not just about building more agents.

It is about building the right AI operating model around them.

AI Agents Are Powerful, But They Need Structure

Most AI projects begin with excitement.

A team sees a manual process. They imagine how AI could make it faster. They build an agent to handle part of the work. The demo looks promising. The output feels useful. Everyone agrees there is potential.

Then real operations begin.

The agent does not always know which data source is correct. The business team is not sure who should approve its output. The engineering team is asked to fix edge cases that were never defined. The compliance team wants more visibility. The operations team wants the agent inside the tools they already use.

Slowly, the project loses momentum.

The issue is not always the AI model. In many cases, the model is doing what it was asked to do. The real problem is that no one redesigned the business process around it.

AI agents do not create value simply by existing. They create value when they are placed inside a clear workflow, supported by clean data, connected to business rules, monitored by people, and measured against real outcomes.

This is where an AI operating model becomes essential.

What Is an AI Operating Model?

An AI operating model is the structure that explains how AI works inside the business.

It defines who owns the AI system, where it fits into the workflow, what data it uses, how decisions are reviewed, how errors are handled, and how success is measured.

In simple terms, it answers the questions most AI projects avoid at the beginning.

Who is responsible if the AI output is wrong?

Which team manages the workflow?

Which systems does the AI need to connect with?

What should be automated, and what still needs human review?

How do we know the AI is actually improving the business?

Without these answers, AI implementation becomes fragile. The company may have advanced tools, but the operating structure remains unclear.

That is when AI becomes busy work instead of business value.

A strong AI operating model does not slow innovation down. It gives innovation a path to scale. It helps teams move from isolated experiments to production-ready AI systems that people can trust and use every day.

Why AI Agents Fail Without Workflow Design

One of the biggest mistakes companies make is adding AI to a broken process without changing the process itself.

If a workflow is messy, AI will not automatically fix it. It may even make the problem more visible.

For example, a company may build an AI agent to support sales teams by summarizing leads and recommending follow-ups. On the surface, this sounds useful. But if the CRM data is incomplete, lead ownership is unclear, and sales managers do not trust automated recommendations, the agent will struggle to deliver value.

The problem is not the agent.

The problem is the workflow around the agent.

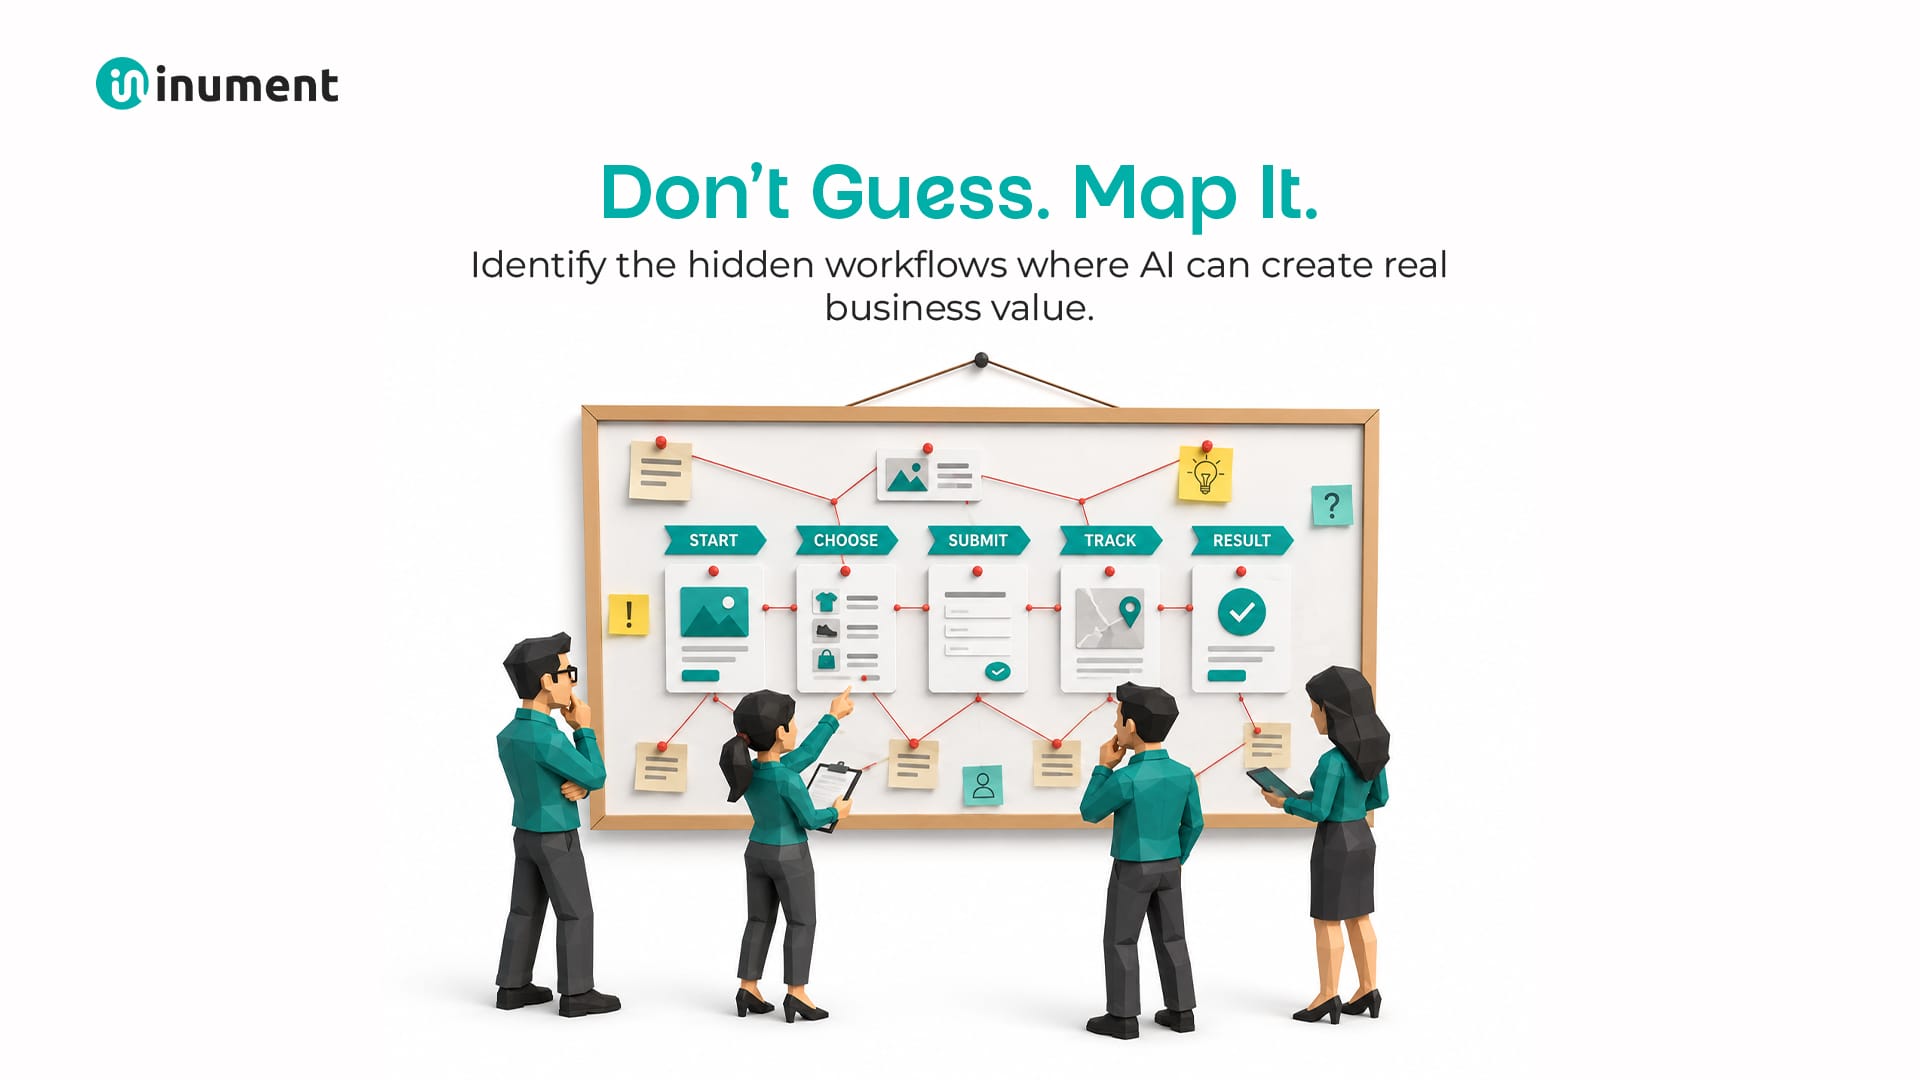
AI workflow automation works best when the process is clearly mapped before automation begins. The business needs to understand each step, each handoff, each decision point, and each source of friction.

Then AI can be placed where it actually helps.

It can reduce repetitive work. It can speed up review. It can organize evidence. It can recommend next actions. It can support teams without replacing the judgment they still need to apply.

But this only works when the workflow is designed with intention.

Ownership Is the Missing Layer

AI projects often fail because everyone is interested, but no one truly owns the outcome.

The product team may define the use case. The engineering team may build the system. The operations team may use it. The leadership team may expect ROI. But when something goes wrong, ownership becomes unclear.

A strong AI operating model fixes this.

It defines business ownership and technical ownership from the start.

Business owners decide what success looks like. They define the process, the rules, and the acceptable level of risk. Technical owners make sure the system is stable, secure, integrated, and maintainable.

Both sides need to work together.

AI cannot scale if it lives only with the innovation team. It also cannot scale if it is treated only as an engineering task. It needs shared ownership across business, product, operations, data, and technology.

That is how AI moves from a promising demo to a reliable business system.

Clean Data Still Decides the Quality of AI

AI agents are only as useful as the information they can access.

If the data is outdated, duplicated, incomplete, or spread across disconnected systems, the agent will produce weak results. It may sound confident, but confidence is not the same as accuracy.

This is why data readiness is a core part of AI implementation.

Companies need to know which data sources matter, who maintains them, how often they are updated, and what rules control access. They also need to decide what the AI can use, what it should ignore, and what requires human validation.

This does not mean every company needs perfect data before using AI.

It means companies need a practical data strategy around each AI use case.

For some workflows, a limited but clean dataset is better than a large messy one. For others, integration across multiple systems may be necessary. The key is to design the AI system around the reality of the business, not around a perfect version of the business that does not exist.

Human Review Is Not a Weakness

Some companies treat human review as a sign that AI is not advanced enough.

That is the wrong way to think about it.

In many business workflows, human review is exactly what makes AI safe, useful, and trusted. AI can process information quickly. It can detect patterns. It can prepare recommendations. But people still need to make judgment calls, especially when the decision affects customers, employees, revenue, risk, or compliance.

The best AI operating model does not remove humans from every step.

It places humans where their judgment matters most.

This is especially important in areas like hiring, finance, legal operations, healthcare support, enterprise sales, and customer experience. In these workflows, AI should organize the evidence, reduce manual effort, and improve decision quality. But the final responsibility should remain clear.

Human-in-the-loop design is not a temporary phase. It is part of building trustworthy AI systems.

Integration Turns AI From a Tool Into a System

A standalone AI agent may be useful for a small task, but it rarely changes the business on its own.

To create real value, AI must connect with the systems people already use. That may include CRMs, ERPs, HR platforms, ticketing systems, document storage, analytics tools, communication platforms, and internal databases.

This is where many AI projects become difficult.

The demo is simple. The real implementation is not.

A production-ready AI system needs secure APIs, workflow triggers, permission controls, monitoring, fallback logic, and performance tracking. It must handle real users, real data, real exceptions, and real business pressure.

This is why an AI engineering team matters.

AI transformation is not just about choosing the right model or tool. It is about engineering the full system around the model. That includes architecture, integration, security, testing, deployment, and continuous improvement.

Without strong engineering, even a good AI idea can stay stuck in prototype mode.

What a Strong AI Operating Model Should Include

A practical AI operating model should be simple enough for teams to understand and strong enough to support scale.

It should begin with a clear use case. The company needs to know what problem the AI system is solving and why that problem matters.

Then it should define the workflow. The team should map what happens before AI, what AI will do, what happens after AI, and where people need to review or approve the output.

Next, it should define ownership. Business and technical responsibilities must be clear. Someone must own the outcome, not just the tool.

It should also define data rules. The system needs trusted data sources, access controls, update logic, and quality checks.

It should include integration planning. AI must connect with the tools and systems where work already happens.

It should include monitoring. Teams need to track performance, accuracy, usage, errors, and business impact.

Finally, it should include a feedback loop. AI systems should improve over time based on real usage, not assumptions from the first build.

This is how companies move from AI experiments to business automation that actually works.

A Practical Example: From Agent to Operating Model

Imagine a company that wants to use AI to improve customer support.

The first idea may be simple: build an AI agent that answers customer questions.

That may help, but it is not enough.

A better approach starts by looking at the full support workflow. What types of questions come in? Which ones are repetitive? Which ones require human judgment? Where is customer data stored? When should a ticket be escalated? How should the team measure improvement?

Once the workflow is clear, the AI agent can be designed properly.

It may answer simple questions using approved knowledge base content. It may summarize complex tickets before sending them to a human agent. It may detect urgent cases based on customer history. It may suggest responses but requires human approval for sensitive issues. It may update the CRM after a case is resolved.

Now the AI agent is not just a chatbot.

It is part of a support operating model.

The company can measure response time, resolution quality, escalation rate, customer satisfaction, and agent productivity. The support team knows when to trust the AI and when to step in. The engineering team knows how the system is performing. Leadership can see whether the AI investment is creating value.

That is the difference between using AI and operating with AI.

Inument’s Point of View

At Inument, we believe the next phase of AI transformation will be won by companies that combine strong business thinking with strong engineering execution.

AI ideas are easy to discuss. AI agents are easier to build than they were a few years ago. But production-ready AI still requires serious work.

It requires workflow design. It requires system integration. It requires clean architecture. It requires human review points. It requires scalable delivery teams that can move fast without creating fragile systems.

This is where Inument helps companies.

We support businesses that want to move beyond AI experiments and build AI systems that work inside real operations. That may mean designing an AI workflow automation layer, building custom AI agents, integrating AI into existing platforms, or extending an internal team with experienced AI engineers.

The goal is not to chase AI trends.

The goal is to build systems that reduce friction, improve decision-making, and create measurable business value.

That is what production-ready AI should do.

The Companies That Win With AI Will Operate Differently

In 2026, the companies that win with AI will not be the ones testing the highest number of tools.

They will be the ones building the strongest operating models around AI.

They will know where AI fits. They will know who owns it. They will know how data flows. They will know when people review decisions. They will know how systems connect. They will know what success looks like.

AI agents will still matter. But they will not be the full story.

The real advantage will come from turning AI agents into reliable business systems.

So the question for leaders is simple.

Are your AI agents just another set of tools, or are they part of a real AI operating model built to scale?

If the answer is unclear, that is where the next stage of work should begin.

About the Author

Safkat Nirjash

Safkat Nirjash

Want to Build Your Dream Tech Team? Hire Now!

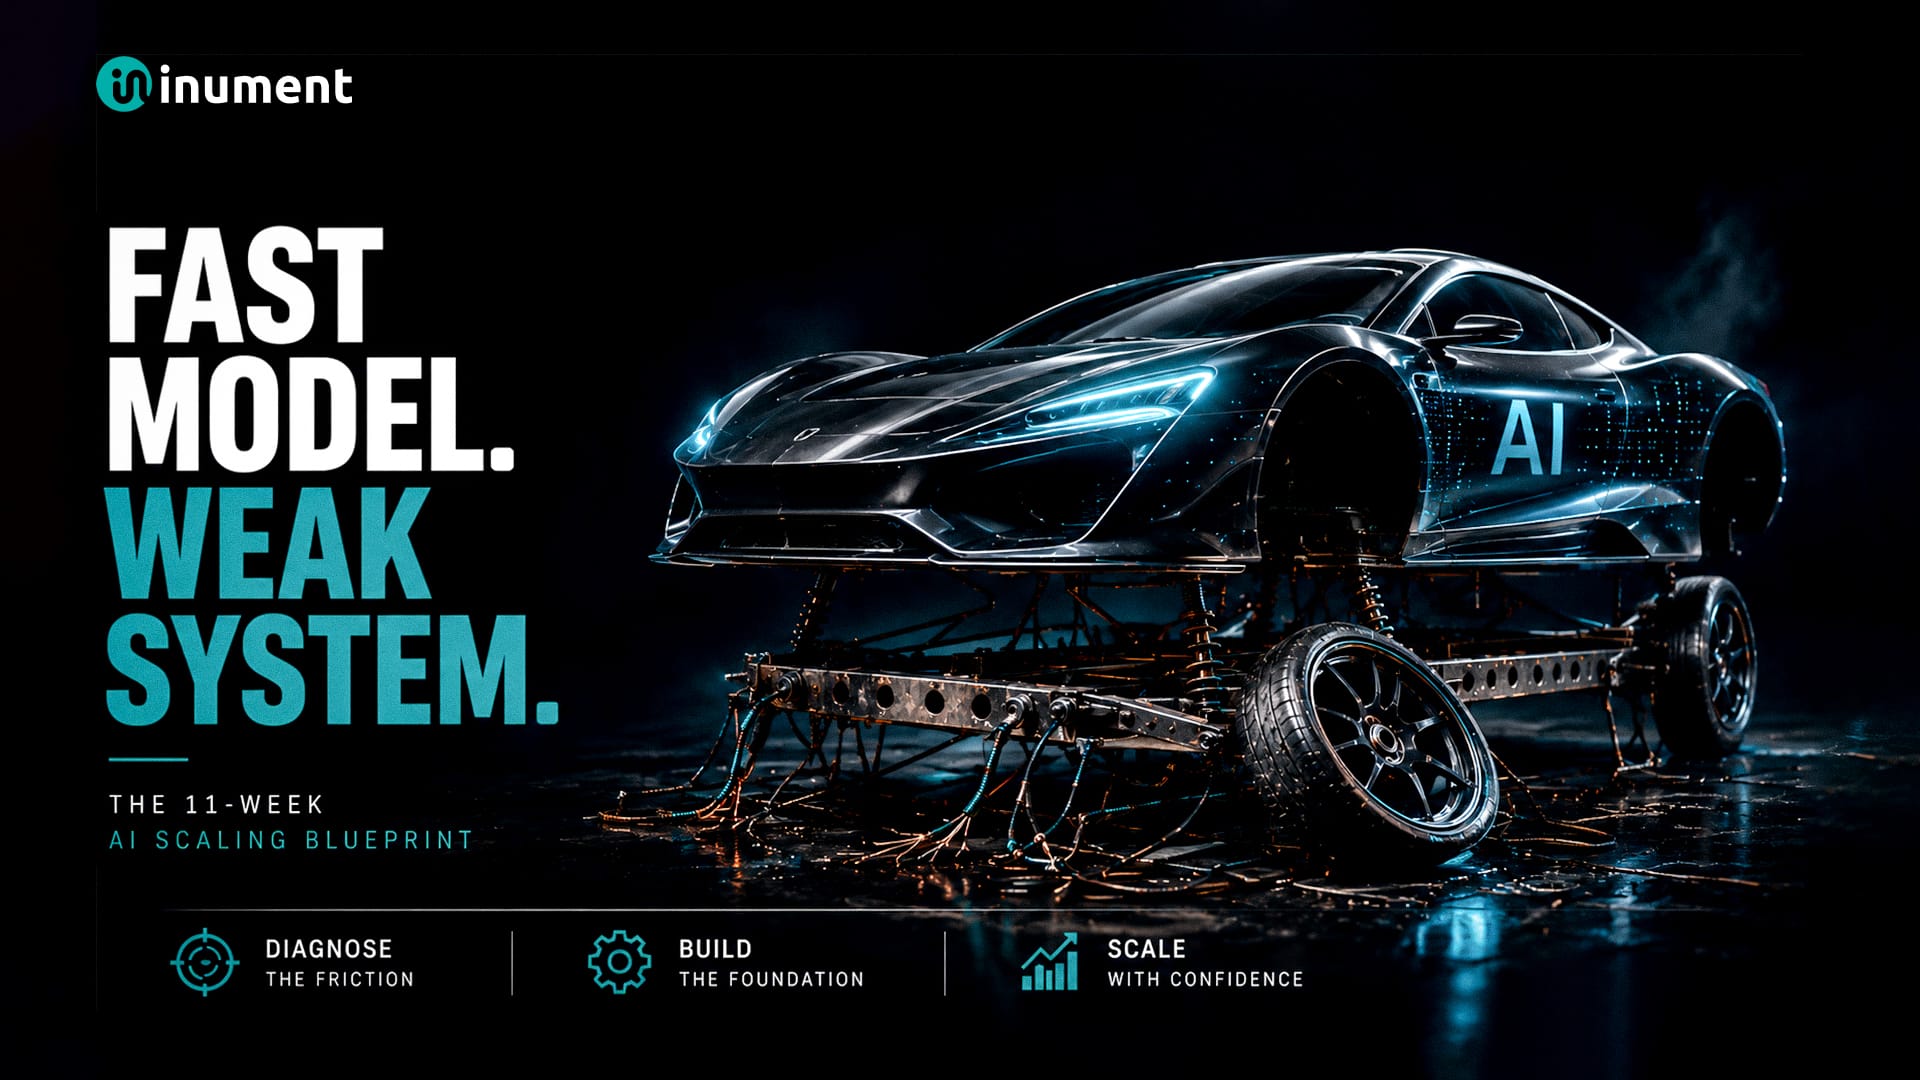
Scale Custom AI Agents in 11 Weeks Without System Friction

Scale Custom AI Agents in 11 Weeks Without System Friction

13 July 2026

|

IconInument

Icon Icon Icon
Most AI Projects Dont Fail They Suffocate

Most AI Projects Don’t Fail. They Suffocate

They suffocate under slow pipelines, under-resourced teams, tangled integrations and infrastructure that never carried the weight of real-world AI workloads.

In 2026, the companies winning with AI are not the ones with the biggest budgets or the boldest vision statements. They are the ones with a repeatable, structured execution system, one that removes friction before it compounds into paralysis.

This is that system.

What follows is Inument’s proven 11-week blueprint built from hundreds of engagements across Europe, the USA, the UK, Australia, and Asia to scale custom AI agent development and permanently eliminate the system friction that is quietly strangling your product’s growth.

Eleven weeks. Three phases. One operating model that changes everything after it.

Takeaway: Print this blueprint. Share it with your CTO. The gap between AI ambition and AI delivery in 2026 is not a talent problem; it is a structural problem. This document closes that gap.

Why 2026 Is the Year the Blueprint Becomes Non-Negotiable

For the last three years, “move fast” was enough of a strategy.

It no longer is.

Enterprise clients in London, Chicago, Sydney, and Singapore are no longer impressed by demos. They are signing contracts with vendors who can prove operational maturity and teams that can deliver generative AI integration for enterprise workflows reliably, at scale, and within regulatory boundaries.

The numbers tell the story clearly. According to 2026 industry data:

  • 63% of enterprise AI projects fail to reach production not because the model was wrong, but because the surrounding system was not ready.
  • The global market for AI staff augmentation services is projected to exceed $47 billion in 2026, driven entirely by the gap between AI ambition and available in-house execution capacity.
  • Teams that follow a structured scaling framework reduce their time-to-production by an average of 38% compared to teams operating on ad hoc roadmaps.

Think of system friction like rust on a high-performance engine. The engine might still run. But every mile costs more than it should, and eventually the rust wins.

The 11-week blueprint is your rust remover.

Takeaway: Before Week 1 begins, benchmark your current time-to-production for AI features. That number is your baseline. By Week 11, the project should be unrecognisable.

Phase One: Weeks 1-3 Diagnose the Friction and Build the Foundation

Week 1: The Friction Audit

You cannot fix what you have not named.

Week 1 is entirely dedicated to mapping every point of system friction across your current stack infrastructure bottlenecks, integration failures, testing gaps, documentation black holes, and team capability mismatches.

For teams currently running software development outsourcing in 2026 models, this audit also surfaces the handoff friction, the invisible delays that live in the gap between your in-house team and your external partners.

Inument’s friction audit framework covers five dimensions: infrastructure readiness, team capacity, pipeline automation, data quality, and compliance posture. For clients with FinTech software regulatory compliance obligations or ethical AI implementation for FinTech requirements, that last dimension alone typically reveals two to three critical gaps before a single line of new code is written.

Deliverable: A prioritised friction map with each issue scored by impact and remediation cost.

Takeaway: Block the entire first week for this audit. Do not skip it to accelerate delivery. Teams that skip the audit spend Weeks 6 and 7 putting out fires that the audit would have prevented.

Week 2: Team Architecture and Gap Analysis

Once you know where the friction lives, you need to know whether your current team can remove it.

In 2026, the honest answer for most scaling organisations is: not entirely, not quickly enough and not without help.

This is where AI staff augmentation services become a strategic lever rather than a staffing transaction. The question is not “Do we need more people?” The question is “Which specific capability gaps are creating the most friction, and what is the fastest way to close them?”

Common gaps Inument identifies at this stage include:

  • No in-house capacity to hire LLM engineers in 2026 at the speed the roadmap demands.
  • Over-reliance on a single senior developer for MLOps consulting services decisions.
  • No hiring strategy for remote DevOps engineers for CI/CD pipeline ownership.
  • Missing hiring Python AI specialists or vetted Node.js developers for hire to own model serving and API layers.

The benefits of IT staff augmentation in 2026 are measurable here: augmented teams reach full productivity 40% faster than traditional hires, with no notice periods, no onboarding overhead, and full accountability from Day 1.

Deliverable: A team gap matrix mapping each friction point to the required capability and the fastest path to closing it in-house hire, augmentation, or nearshore vs offshore staff augmentation model.

Takeaway: Do not default to hiring full-time for every gap. Augmentation delivers faster results with lower fixed costs for specialist roles, such as hiring AWS-certified cloud architects or augmented reality developers.

Week 3: Infrastructure Baseline and Stack Decisions

Week 3 is where architecture decisions get locked.

This is the most consequential week of Phase One. Stack decisions made here determine your ceiling for the next three years. Teams that choose poorly – selecting low-code platforms without a low-code vs custom software cost analysis, or skipping a serverless architecture consulting reviews build ceilings into their infrastructure before they build their first production feature.

Inument’s infrastructure baseline protocol covers:

  • Scalable cloud-native app development readiness assessment.
  • Multi-tenant SaaS architecture design requirements for enterprise client segregation.
  • Microservices migration strategy for teams still running monolithic legacy systems.
  • Legacy system modernization services scope for inherited technical debt.

For clients building custom AI agent development pipelines, Week 3 also includes a model serving architecture review, ensuring that the infrastructure can handle real-world inference loads without the latency spikes that kill enterprise SLAs.

Deliverable: A locked infrastructure blueprint with documented decisions, trade-off rationale, and a three-year scalability projection.

Takeaway: Bring your dedicated software development team into these decisions, not just your architects. The people who will maintain the system should understand why it was built the way it was.

Phase Two: Weeks 4-8 Build, Integrate, and Harden

Week 4–5: Core Pipeline Development

With the foundation locked, Weeks 4 and 5 move into active development of the core AI pipeline.

For most clients, this means building or refactoring three interconnected layers simultaneously: data ingestion and preprocessing, model training and fine-tuning, and API serving and integration.

Teams deploying natural language processing services, AI-powered automation for logistics, or predictive analytics solutions for retail at this stage share a common challenge: the gap between a model that performs well in evaluation and a model that performs well in production under variable real-world conditions.

Inument’s approach during this phase mirrors the construction of a suspension bridge. The cables your data pipelines and model-serving layers must carry load before the deck your application features are ever attached. Build the cables first. Test them under stress. Then build the deck.

Teams that reverse this order (and many do) discover in Week 9 that their beautiful application is hanging from fraying wire.

Deliverable: A working, tested core pipeline with documented input/output contracts for every integration point.

Takeaway: Invest disproportionately in pipeline observability during these two weeks. Every hour spent on monitoring now saves ten hours of debugging in production later.

Week 6: Integration Sprint Connecting AI to Your Existing Stack

Week 6 is the most technically complex week of the entire blueprint.

This is where the AI pipeline connects to your existing product stack, whether that is a custom SaaS application development platform, a React JS development agency frontend, a React Native development company mobile layer, or an enterprise ERP system that was never designed with AI integration in mind.

Common integration friction points at this stage:

  • Custom mobile app development services for clients needing real-time AI inference on iOS and Android app development platforms with sub-200 ms response requirements.
  • Progressive Web App (PWA) development teams manage state synchronisation between AI agent outputs and frontend UI layers.
  • E-commerce mobile app specialists integrating recommendation engine outputs with legacy inventory and pricing systems.
  • Healthcare mobile app development teams navigating data residency requirements while connecting to cloud-hosted model endpoints.

For clients with blockchain development for supply chain components, Week 6 also includes smart contract integration testing, ensuring that AI agent decisions that trigger on-chain transactions do so with the correct validation logic.

Deliverable: A fully integrated system with end-to-end testing documentation across all integration points.

Takeaway: Do not treat integration as the last 10% of the project. Treat it as a first-class engineering concern from Week 1. The teams that discover integration complexity in Week 6 rather than Week 10 are the teams that deliver on time.

Week 7–8: Security, Compliance, and Quality Hardening

Speed without security is not delivery. It is a liability.

Weeks 7 and 8 are dedicated entirely to hardening the system against the threats and compliance obligations that will define whether your enterprise clients sign long-term contracts or walk away after the first audit.

Inument’s hardening protocol at this stage includes:

  • Cybersecurity audit for small businesses and enterprise-grade penetration testing across all AI API endpoints.
  • Enterprise mobile security solutions implementation for clients with mobile AI agent deployments.
  • Quality assurance and software testing automation, including regression suites, load testing, and adversarial input testing for LLM-powered features.
  • FinTech software regulatory compliance review for clients operating under FCA, SEC, ASIC, or MAS regulatory frameworks.

In 2026, the cost of a security incident involving an AI system is not just financial. It is reputational. A single breach of an AI agent with access to customer data can undo years of Inument reviews and client trust built across multiple markets.

Deliverable: A security and compliance sign-off document with all critical and high-severity findings remediated before Phase Three begins.

Takeaway: Schedule your cybersecurity audit before your go-live date, not after. Audits that happen post-launch find problems that your clients discover first.

Phase Three: Weeks 9-11  Scale, Optimise, and Operationalise

Week 9: Performance Optimisation and Load Testing

Week 9 answers the question every CTO dreads: “What happens when the system actually works?”

Because when a custom AI agent development system works, when it starts delivering real value to real users, usage grows quickly. The infrastructure that handled 500 concurrent users in staging will face 50,000 in production within weeks of a successful enterprise rollout.

Inument’s performance optimisation protocol covers three areas:

  • Scalable cloud-native app development configuration review: autoscaling policies, container orchestration, and cold start elimination for serverless architecture consulting deployments.
  • Mobile app maintenance and support optimisation for clients with hired Flutter developers for cross-platform deployments that handle AI-powered features.
  • Model inference optimisation quantisation, caching strategies, and batching configurations that reduce per-request cost by 30–60% at scale.

Deliverable: A load-tested system with documented performance benchmarks at 1x, 10x, and 100x expected production load.

Takeaway: If your system cannot survive a 10x traffic spike in Week 9, it will not survive a successful product launch. Test now while the cost of failure is a delayed sprint, not a downed production system.

Week 10: Team Handover and Knowledge Transfer

The most overlooked week in every AI scaling engagement.

Inument dedicates Week 10 entirely to structured knowledge transfer ensuring that your internal team fully owns and understands what has been built, why architectural decisions were made, and how to extend the system without creating the technical debt that kills Year 2 products.

For clients running a scale engineering team on demand or temporary IT staffing solutions models, this week also includes documentation of all augmented team contributions so that when contractors roll off, they do not take critical system knowledge with them.

The knowledge transfer package includes architecture decision records, runbook documentation, incident response playbooks, and a model governance framework for teams with ethical AI implementation for FinTech or other regulated AI deployment requirements.

Takeaway: Knowledge transfer is not a nice-to-have. It is the difference between a project and a capability. A project ends. A capability compounds.

Week 11: Go-Live and the Operational Resilience Handshake

Week 11 is not the end. It is the starting line.

Go-live week at Inument includes a structured operational resilience review a formal handshake between the delivery team and the client’s ongoing operations function that covers monitoring protocols, escalation paths, SLA commitments, and the 20% debt-repayment discipline that prevents the Year 2 death spiral.

For clients across the best IT outsourcing countries in Asia, including Inument’s own enterprise software development operations in Dhaka, this handshake also formalises the ongoing support model, whether that is a retained dedicated software development team, a digital transformation consulting advisory engagement, or a hybrid offshore AI development company partnership.

Deliverable: A live, monitored, fully documented production system with an operational playbook that your team can run independently from Day 1.

Takeaway: Celebrate the launch for exactly one day. Then start Week 1 of your next cycle. In Year 2, Inument calls the teams that treat go-live as the end.

Real-World Result: From Friction to Scale in 11 Weeks

One of Inument’s enterprise logistics clients in the UK entered Week 1 with a partially built AI dispatch optimisation system, a team of six engineers carrying an estimated $1.4M in technical debt, and a client contract that required production deployment within 90 days.

By applying this exact blueprint with Inument providing AI staff augmentation services to close three critical team gaps, a microservices migration strategy to decompose a monolithic legacy system, and a full quality assurance and software testing automation layer, the team delivered to production in 76 days.

Post-launch metrics after 60 days in production: 34% reduction in dispatch error rate, 28% improvement in route optimisation efficiency, and a client contract renewal signed at 2.4x the original contract value.

The friction did not disappear on its own. It was systematically removed, week by week, with a blueprint that left no room for ambiguity.

Takeaway: The 11-week blueprint is not theoretical. It has a track record. Search Inument Solution Ltd reviews to read what clients across Europe, the USA, the UK, Australia, and Asia say about the results.

The Closing Statement: Systems Beat Sprints. Always

In 2026, every company is an AI company or it is becoming one, or another company is replacing it.

The question is no longer whether to build custom AI agent development capabilities. The question is whether you build them on a foundation that scales or on a foundation that collapses under its ambition in Year 2.

Eleven weeks is not a long time. But it is exactly long enough to replace system friction with system resilience if you follow the blueprint with discipline, staff the gaps honestly, and treat operational readiness as a first-class engineering concern from Day 1.

At Inument, we do not build projects. We build capabilities. And we build them to last.

The sprint era is over. The systems era has begun. Build accordingly.

Start Your 11-Week Engagement Today

Whether you need a full offshore AI development company partnership, targeted AI staff augmentation services to close critical capability gaps, or a digital transformation consulting engagement to redesign your AI foundation, Inument has the framework, the team, and the 11-week blueprint ready to deploy.

Visit inumentsolution.com to book your Week 1 friction audit.
Search Inument to see what teams across four continents say about the results.

About the Author

Safkat Nirjash

Safkat Nirjash

Want to Build Your Dream Tech Team? Hire Now!

Why ‘Move Fast, Break Things’ Is Killing Your Custom AI Agent Development Before Year 2?

Why ‘Move Fast, Break Things’ Is Killing Your Custom AI Agent Development Before Year 2?

19 June 2026

|

IconInument

Icon Icon Icon
Why_Move_Fast_Break_Things_Is_Killing_Your_Custom_AI_Agent_Development_Before_Year_2_inument

The Bold Claim Nobody Wants to Hear

Ninety-one percent of AI startups that failed in 2025 had one thing in common, and it wasn’t a bad idea.

It was a good idea, built on a crumbling foundation. A 2025 post-mortem audit of 47 failing startups confirmed that technical debt not poor market fit was the primary cause of their collapse. The average cost per company: $2M–$3M in wasted salaries and evaporated revenue.

In 2026, that number is climbing. The explosion in demand for custom AI agents from enterprise clients in London, New York, Sydney, and Singapore has pushed development teams into a familiar trap: ship fast, patch later, and pray Year 2 never arrives.

It always arrives.

Takeaway: If you are currently celebrating your sprint velocity, check what’s hiding underneath it. Speed without structure is not momentum; it’s a countdown.

Why This Matters More in 2026 Than Ever Before

The AI market has fundamentally changed the stakes of software development.

Enterprise buyers across the US, UK, Europe, and Australia are no longer debating whether to adopt AI. They are racing to implement it demanding generative AI integration for enterprise workflows, deploying AI-powered automation for logistics pipelines, and building predictive analytics solutions for retail at a pace that would have been unthinkable three years ago.

This pressure cascades directly onto development teams. Teams are scrambling to hire LLM engineers in 2026, stand up MLOps consulting services, and deliver production-ready AI agents simultaneously, often with under-resourced squads operating across multiple time zones.

The result is not innovation. It is the illusion of innovation, built on a foundation that will crack under the weight of its ambition in twelve to eighteen months.

According to Gartner’s 2026 IT spending forecast, the average enterprise now loses 21%–40% of its total IT budget to technical debt management. For companies pursuing software development outsourcing in 2026 from the best IT outsourcing countries in Asia, including In Bangladesh, India, and Vietnam, this overhead has become a board-level conversation, not just an engineering footnote.

Takeaway: Audit your current build-to-maintenance ratio today. If you are already past 50/50, you are inside the spiral, and the window to course-correct without a painful rewrite is closing.

The Four Horsemen of Product Decay

Technical debt is not just messy code. Think of it as four separate payday loans, each at a different interest rate, compounding silently in the background while your team celebrates another release.

Inument categorizes the decay into four distinct areas that paralyze engineering teams across every market, from a React JS development agency in Dhaka to a React Native development company in Berlin.

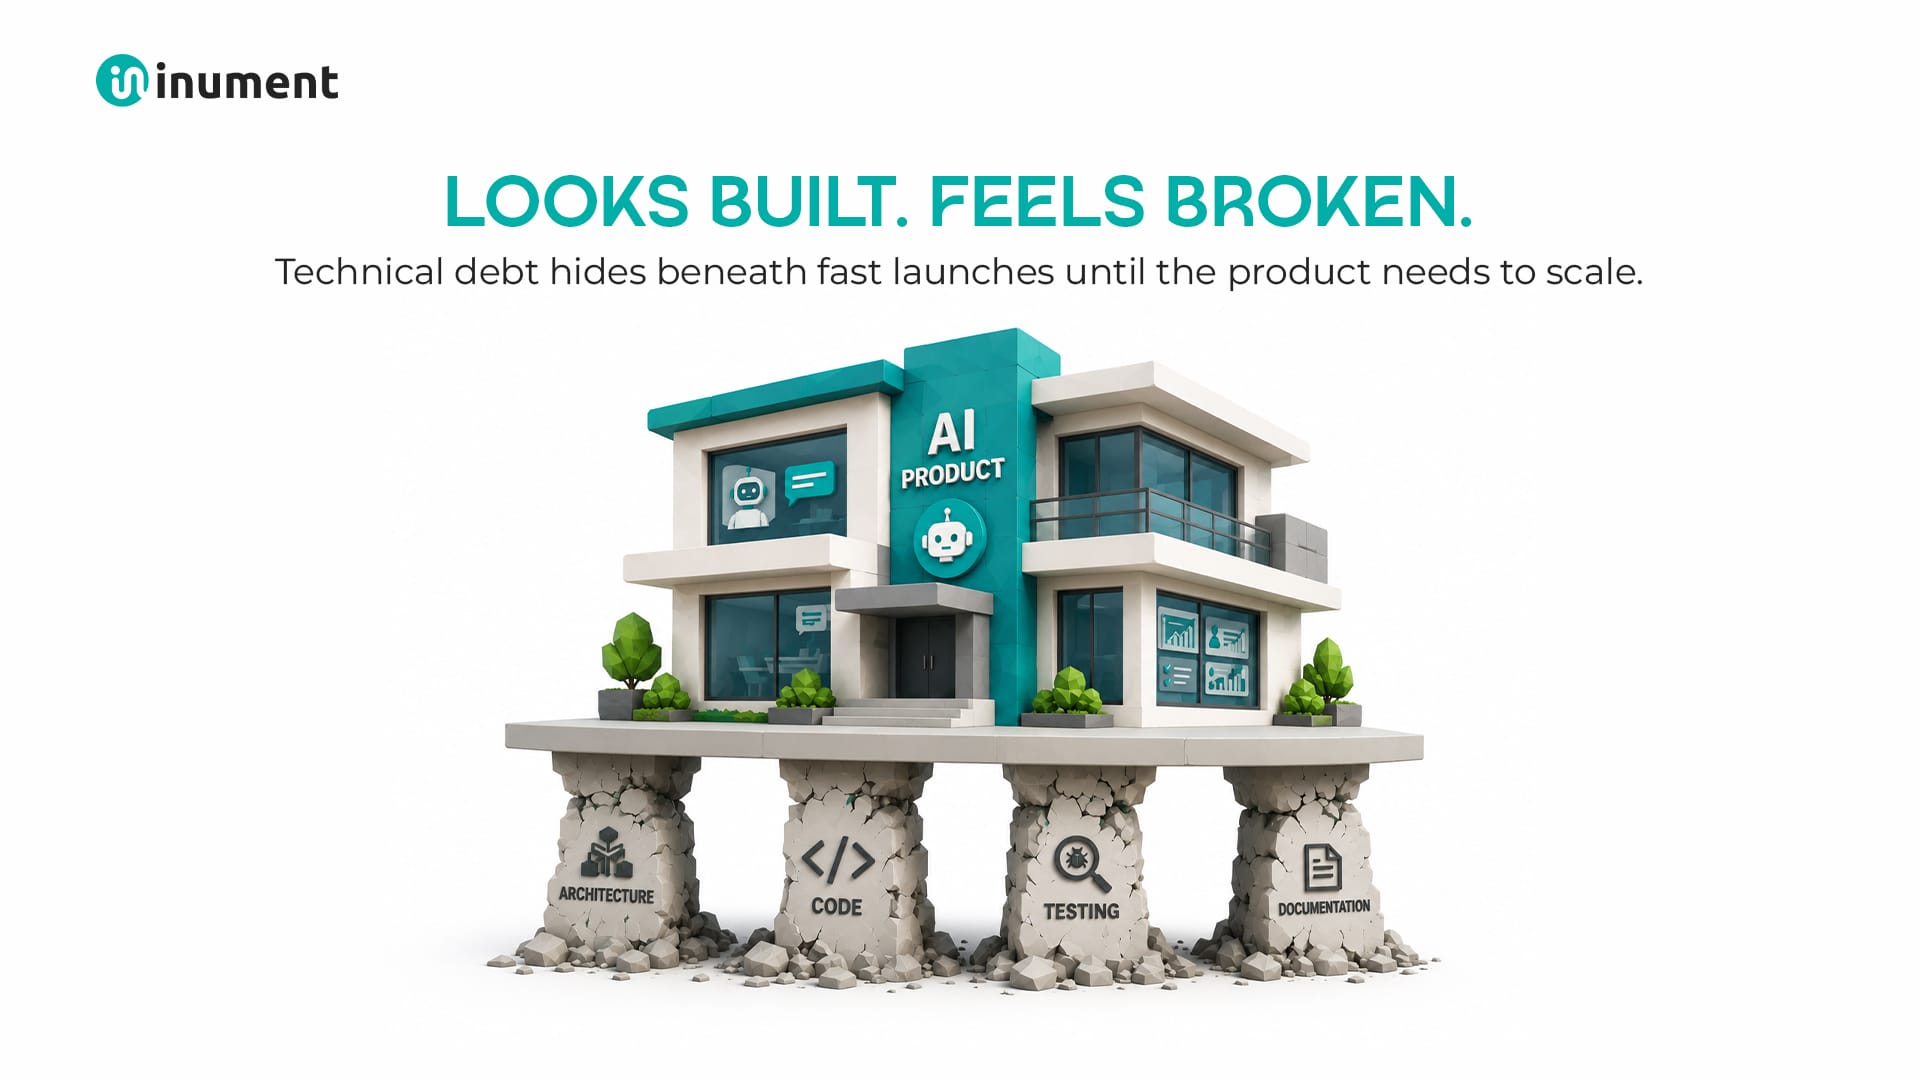
1. Architectural Debt

These are the sub-optimal system design decisions baked in during the rush: tight coupling, monolithic structures, no microservices migration strategy, and zero consideration for future multi-tenant SaaS architecture design. When you eventually need to scale, you discover you have built a house of cards, not a platform.

2. Code Debt

Quick-and-dirty shortcuts that compound into “spaghetti logic”. When you later bring in hired Python AI specialists or vetted Node.js developers for hire to extend the system, they spend their first two weeks reverse-engineering what your original team built in a 48-hour sprint. That onboarding cost is invisible on your roadmap but very visible on your burn rate.

3. Testing Debt

The 2025 audit found that 91% of failing startups had no automated tests whatsoever. Zero. Every new feature deployed into a system like this is a game of Russian roulette. Quality assurance and software testing are not glamorous. It is the difference between scaling to 100,000 users and crashing at 10,000.

4. Documentation Debt

When critical business logic lives only inside one developer’s head, you are one resignation letter away from catastrophe. As teams grow, particularly in AI staff augmentation services or IT staff augmentation for startup models where contributors rotate, “archaeological debugging” becomes a full-time job. It gets more expensive every quarter.

Takeaway: Before your next sprint planning session, assign one owner to map your current debt across all four categories. A one-hour audit today prevents a three-month crisis in Year 2.

The Year 2 Death Spiral: Where Budgets Go to Die

Here is the math that most founders only see in hindsight.

Timeline           

Innovation Budget

Maintenance  Budget

State of the Product

Year 1

70% – 80%

20% – 30%

The Sprint: high velocity, rapid releases, and the “momentum” phase.

Year 2

40% – 50%

50% – 60%

The Flip: maintenance becomes the majority. Debt knocks at the door.

Year 3 

15% – 25%

75% – 85%

The Legacy: total gridlock. Innovation is a minor detail.

The transition from Year 1 to Year 2 is not gradual. It is a cliff edge.

Once your maintenance budget eclipses your build budget, your capacity for developing custom AI agents, releasing new features, or responding to enterprise client requests collapses almost overnight. The team that was shipping weekly is now triaging daily.

For companies with FinTech software regulatory compliance obligations or those delivering ethical AI implementation for FinTech clients, this is not merely a productivity problem; it is a legal liability. Brittle systems fail audits. Failing audits kill contracts.

2026 Data Point: Professional developers now spend 42% of their working week maintaining or fixing existing bad code rather than building new features. In typical SMBs, 72% of the IT budget goes toward basic operations, leaving just 28% for growth.

Takeaway: Calculate your own “standing-still cost”. Multiply your total monthly developer payroll by 0.42. That figure represents what you are currently paying to not fall behind, not to get ahead.

The $6 Trillion Problem: A Board-Level Risk, Not an Engineering One

Global technical debt reached $6 trillion in 2026.

That number is not a warning from engineers to CFOs. It is a warning from CFOs to boards. And it is playing out identically whether you run a custom SaaS application development firm in Manchester, an iOS and Android app development agency in Melbourne, or an enterprise software development company in Dhaka.

The financial anatomy of the problem breaks down like this:

  • The Innovation Tax: Average firms now lose 21%–40% of IT budget to debt management annually.
  • The Productivity Drain: Developers spend 42% of their week on maintenance versus creation.
  • The SMB Trap: 72% of small and medium business IT budgets go to “keeping the lights on”.

For teams considering low-code vs custom software cost trade-offs, this data matters enormously. Low-code platforms promise speed. Deliberate serverless architecture consulting or a scalable cloud-native app development strategy is necessary; otherwise, low-code platforms create the same debt categories, but with less visibility into where the bodies are buried.

Takeaway: Bring your technical debt conversation out of the engineering standup and into your next board or investor update. Frame it in dollars, not tickets.

Real-World Case Study: eBay and the Cost of Waiting

eBay is one of the best learning examples in modern software history. Not because they failed, but because they almost did.

At a critical growth juncture, legacy architectural debt caused severe latency during checkout. Every second of checkout delay translates to measurable revenue loss at eBay’s transaction volume. The root cause was not a lack of talent. It was years of prioritizing new features over foundational integrity.

Their recovery required a multi-year commitment to modernization rather than to developing new features. It was an extraordinarily difficult sell to stakeholders conditioned to celebrate shipping velocity. But they recovered nearly half of their trapped engineering value and restored the scaling capabilities that debt had frozen.

The Microsoft parallel is less discussed but equally instructive. Microsoft’s pattern of rapid feature deployment shipping with known bugs, then patching in waves, has conditioned hundreds of millions of users to delay OS and software updates. The market learned their pulse. Slow adoption became the invoice Microsoft receives for moving too fast.

This identical dynamic plays out in startups delivering healthcare mobile app development, e-commerce mobile app infrastructure, or progressive web app (PWA) development industries, where user trust, uptime, and compliance are essential requirements, not differentiators.

Takeaway: Ask your team honestly: are your users already waiting for your patches before they update? If the answer is yes, your users have already noticed what you haven’t fixed yet.

The 20% Rule: Inument’s Framework for Operational Resilience

Inument does not just diagnose the problem. We provide the framework to survive it.

The cornerstone of what we call ‘digital accountability’ is the 20% Rule: allocate one focused day per week or 20% of every sprint to structured debt repayment across three core pillars.

This is not downtime. This is the highest-ROI investment your engineering team can make in Year 1.

Pillar 1: Refactor Architectural Bottlenecks

Decouple tightly integrated services. Modularize legacy components so each can be updated independently. For teams building AI-powered automation for logistics, deploying natural language processing services at scale, or managing multi-tenant SaaS architecture design, this modularity is not optional; it is the prerequisite for everything that comes after.

Inument helps you identify and untangle these dependencies before they become Year 2 emergencies. Teams that complete this work reclaim, on average, 20% of lost engineering velocity within 90 days.

Pillar 2: Automate Quality Assurance

If you carry testing debt, you must spend your 20% time building automated regression suites immediately.

For teams that hire remote DevOps engineers, operate nearshore vs offshore staff augmentation models, or scale engineering teams on demand across multiple geographies, manual QA is not just slow; it is structurally incompatible with distributed development. Inument’s automated testing solutions replace manual QA pipelines, removing the single biggest drag on modern distributed teams.

Pillar 3: Modernize Infrastructure and Data

Research shows that moving to cloud-native solutions and remediating data lineage reduces technical debt by 18% over five years. For companies with FinTech software regulatory compliance requirements or cybersecurity audits for small business obligations auditable, documented data flows are also a legal requirement, not just a best practice.

For teams currently evaluating hiring AWS-certified cloud architects or planning a legacy system modernization services engagement, this pillar is where the long-term compounding returns live.

Takeaway: Start your 20% allocation in the next sprint. Pick the single highest-risk debt category from your audit, assign a dedicated owner, and measure velocity before and after 90 days. The numbers will do the rest of the convincing.

The Cultural Shift: Building for Business Reality, Not Demo Day

The 20% Rule is not a technical preference for any tech CEO, CTO, or founder, regardless of whether they manage a dedicated in-house software development team or operate a blended model with an offshore AI development company partner. It is a commercial hedge.

Junior developers experience debt-repayment sprints as boring maintenance. Senior engineers know the truth: it is operational resilience. It is the difference between a prototype that impresses in a pitch deck and a product that survives Year 2 without a $2M emergency rewrite.

A team that spends 80% of its time on new features is fast today and paralysed tomorrow. A team that protects 20% for foundations is still shipping confidently in year 3 and still winning clients in year 5.

This principle applies equally whether you are building mobile app maintenance and support contracts for enterprise clients in Frankfurt, delivering blockchain development for supply chain solutions in Singapore, providing augmented reality developer-for-hire services to retail brands in Chicago, or running a SaaS MVP development programme for entrepreneurs in Bristol.

The market does not care about your sprint velocity. It cares about whether your product works reliably, securely, and at scale.

Takeaway: Make operational resilience a named value in your engineering culture, not a footnote in your retrospectives. Teams that name it, fund it, and measure it consistently outperform those that treat it as optional.

A Pragmatic Path Forward

Technical debt is a loan you only have to repay if you need to change the system.

In Year 2, you always need to change everything. Markets shift. User demands evolve. Competitors release features that redefine your roadmap overnight. If your code is brittle, if your architecture cannot bend, you cannot pivot.

If your team’s velocity has dropped by 20% or more in the last quarter, you are in the slowdown. The death spiral has begun, even if the product still looks healthy from the outside.

Whether you are delivering digital transformation consulting to a global logistics firm, building enterprise mobile security solutions for a regulated financial client, or launching a custom mobile app development services offer to startups in the APAC region, the same rule applies: brittle infrastructure is a ceiling you will hit and hit hard.

At Inument, we have seen this pattern across markets in Europe, the USA, the UK, Australia, and Asia. We have helped teams recover from it, and we have helped smarter teams prevent it entirely through structured AI staff augmentation services, rigorous technical debt frameworks, and a principle we call ‘operational resilience’.

The hype of rapid experimentation is over. 2026 is the year of building things that last.

Is your product currently in the momentum phase, or are you already paying for the shortcuts of last year?

Ready to Stop the Spiral?

Inument offers a free technical debt assessment for product teams at every stage. Whether you need a full offshore AI development company partner, targeted AI staff augmentation services to fill critical gaps, or a strategic digital transformation consulting engagement to redesign your foundation, we have the framework, the team, and the track record.

Visit inument.com to book your free assessment.
Read what clients across Europe, the USA, the UK, and Asia say. Search Inument Solutions Ltd reviews to see the results firsthand.

Build fast. But build to last.

About the Author

Safkat Nirjash

Safkat Nirjash

Want to Build Your Dream Tech Team? Hire Now!

Great Code Isn’t Enough: Why Inument’s AI Staff Augmentation Services Need Strong Communication to Deliver ROI

Great Code Isn’t Enough: Why Inument’s AI Staff Augmentation Services Need Strong Communication to Deliver ROI

2 June 2026

|

IconInument

Icon Icon Icon
Great_Code_Isn’t_Enough_Inument's_AI_Staff_outsourcing_is_essential_inument

The biggest software risk in 2026 is not bad code. It is building the wrong thing beautifully.

Companies across Europe, the USA, the UK, Australia, and Asia are investing heavily in AI, cloud, SaaS, automation, and remote engineering teams. But the market has changed. A few years ago, a new app, dashboard, AI chatbot, or automation tool could sound impressive simply because it felt innovative. Today, leaders are asking harder questions.

  • Will it reduce cost?
  • Will it improve revenue?
  • Will it make the team faster?
  • Will customers actually use it?
  • Will it reach production and create measurable ROI?

This is why great code is no longer enough. A dedicated software development team must communicate clearly, understand business priorities, and connect every technical decision to a real outcome.

At Inument, this matters deeply because the work often begins with AI staff augmentation services, custom AI agent development, custom SaaS application development, or support as an offshore AI development company. But behind every technical request, there is always a business question.

Takeaway: In 2026, software teams are not judged only by what they build. They are judged by what the business gains from it.

Why This Topic Matters in 2026

The software market is entering an ROI reckoning. IT spending is growing, AI investment is rising, and enterprises are moving faster. But bigger budgets do not automatically create better products.

The real challenge is alignment.

A company may hire LLM engineers in 2026, hire Python AI specialists, hire remote React developers in 2026, or bring in vetted Node.js developers for hire. These are smart moves when the skills are missing internally. But skilled developers still need strong direction.

A React developer needs to understand the user journey. A Node.js developer needs to understand the workflow behind the API. A Python AI specialist needs to know which decision the model should improve. A DevOps engineer needs to know the uptime, cost, and release expectations.

Without that context, even a strong dedicated software development team can produce output without creating value.

This is especially important for companies comparing nearshore vs offshore staff augmentation. Location, cost, and time zone overlap matter. But communication quality matters more. A low-cost team that does not understand your business can become expensive rapidly.

Takeaway: Before you scale the engineering team on demand, make sure the team understands why the work matters.

The Hidden Problem: Conceptual Bugs

Software teams are trained to find technical bugs. They check broken logic, API failures, slow load times, security gaps, and poor user flows.

But one of the most expensive problems is not a technical bug. It is a conceptual bug.

A conceptual bug happens when the software works, but it solves the wrong problem.

  • The code runs.
  • The interface looks clean.
  • The deployment succeeds.
  • But the feature does not improve the business.

Such scenarios happen more often than teams admit.

A retailer builds a dashboard, but decision-makers still rely on spreadsheets. A logistics company invests in AI-powered automation for logistics, but the manual process behind it remains unclear. A FinTech company adds AI scoring, but ethical AI implementation for FinTech and FinTech software regulatory compliance were not considered early enough. A SaaS startup launches quickly but later discovers that the system needs a multi-tenant SaaS architecture design before it can grow.

In 2026, AI makes this risk bigger. Generative AI can speed up coding, testing, and documentation. But it is less useful when requirements are vague. That means unclear thinking becomes expensive faster than before.

This is why communication must come before development.

Takeaway: Do not only ask, “Can we build it?” Ask, “Are we solving the right problem?”

Correct Code Can Still Fail

Correct code can still fail if the team is misaligned.

One team understands the requirement one way. Another team understands it differently. A business stakeholder assumes one workflow. The developer builds another. A model performs well in testing but fails with real users. A deployment works technically but creates operational confusion.

The software did what it was asked to do. The problem is that the team asked it to do the wrong thing.

This matters even more in advanced technology projects such as generative AI integration for enterprise, custom AI agent development, natural language processing services, predictive analytics solutions for retail, and MLOps consulting services.

These solutions can create real value. But they need clarity.

A custom AI agent should have defined boundaries.
An NLP system should have a clear use case.
A predictive analytics platform should improve a business decision.
An MLOps setup should support monitoring, retraining, governance, and safe deployment.

AI does not remove the need for communication. It increases it.

Think of software like a high-performance car. Great code is the engine. Communication is the steering wheel. Without steering, speed only helps you reach the wrong destination faster.

Takeaway: The more powerful the technology, the more important the alignment.

The Code-First Trap

Many teams think starting development quickly means moving fast.

In reality, starting too early often creates rework.

A product manager requests a feature. Engineers begin building. Then stakeholders add new requirements. Then users behave differently than expected. Then QA finds gaps. Then the architecture needs to change. Then the release date slips.

The team was busy the whole time, but the business did not move forward.

This is the code-first trap.

It affects startups, scale-ups, and enterprises. It also affects companies looking for IT staff augmentation for startups, temporary IT staffing solutions, dedicated software development team support, or software development outsourcing in 2026.

The benefits of IT staff augmentation in 2026 are clear: faster access to talent, flexible scaling, specialized skills, and lower hiring commitment. But staff augmentation should not mean adding random developers to a backlog.

The real value comes when augmented engineers become part of the product thinking.

They should understand the business goal, customer pain, technical risk, release priority, and success metric. That is when AI staff augmentation services become more than capacity. They become a strategic delivery advantage.

Takeaway: Do not add people only to move faster. Add clarity so the team moves in the right direction.

Architecture Should Match the Business Stage

Good engineering is not about using the most fashionable stack. It is about choosing what the business actually needs right now.

A startup may need SaaS MVP development for entrepreneurs, not a complex enterprise system. A growing SaaS company may need scalable cloud-native app development and multi-tenant SaaS architecture design. An established business may need services to modernize legacy systems because old systems are slowing down operations.

Some companies need serverless architecture consulting to reduce infrastructure complexity. Others need a microservices migration strategy because the current platform has become too large and fragile. Some need to hire AWS-certified cloud architects to control cost, security, and scalability.

The same logic applies to mobile.

A company may need custom mobile app development services, an iOS and Android app development agency, a React Native development company, or to hire Flutter developers for cross-platform delivery. But the discussion should not stop at the framework.

The team must also think about mobile app UI/UX design trends in 2026, enterprise mobile security solutions, mobile app maintenance and support, performance, retention, and future scalability.

Healthcare mobile app development needs extra care around privacy, trust, and usability. E-commerce mobile app specialists need to think about conversion, checkout friction, loyalty, and personalization. An augmented reality developer for hire may be useful for certain use cases, but you should only add AR when it improves the user experience.

The best technical decision is not the most advanced one. It is the one that fits the business stage.

Takeaway: Choose architecture based on business reality, not technology fashion.

Quality Is Part of ROI

Quality assurance and software testing are often treated as final steps. That is a mistake.

Quality protects ROI.

A broken release damages trust. A slow app reduces conversion. A weak security model creates risk. A poorly tested SaaS platform increases support costs. A badly monitored AI model can produce unreliable decisions.

In 2026, speed without reliability is not an advantage.

Testing should cover business logic, user experience, performance, integrations, security, and maintainability. For AI systems, it should also include data quality, model drift, accuracy, explain ability, and human review. For cloud-native systems, it should include observability, uptime, rollback planning, and disaster recovery.

This stage is also where services like cybersecurity audits for small businesses, enterprise mobile security solutions, and MLOps consulting services become important. Security, reliability, and governance should not be added after launch. They should be part of the build process.

Even emerging areas such as blockchain development for supply chains need the same discipline. The technology may sound advanced, but the question remains simple: does it reduce fraud, improve traceability, or create operational value?

Takeaway: Software is not finished when it is deployed. It is finished when it performs reliably in the real world.

Practical Breakdown: How to Build with Clarity

Strong communication does not mean endless meetings. It means creating a shared understanding before the team spends expensive engineering time.

Here is a simple framework. Inument recommends:

1. Define the business problem

Before writing code, ask what is currently slow, expensive, risky, or painful. This helps avoid building features that look useful but do not change outcomes.

2. Map the user journey

Every technical feature should connect to a real user action. This is important for SaaS, mobile, retail, healthcare, logistics, and FinTech products.

3. Choose the right delivery model

Compare low-code vs custom software costs carefully. Low-code may work for internal workflows. Custom software may be better when scalability, security, user experience, or competitive advantage matters.

4. Match talent to the roadmap

You may need to hire remote DevOps engineers, hire Python AI specialists, hire LLM engineers in 2026, or hire remote React developers in 2026. But hire based on roadmap needs, not buzzwords.

5. Set success metrics early

Define what should improve after launch: cost, speed, conversion, adoption, uptime, customer satisfaction, or revenue.

6. Review communication weekly

A dedicated software development team should review not only tasks, but also assumptions, blockers, risks, and business changes.

Takeaway: Clear communication is not a soft skill. It is an ROI control system.

Mini Case Study: From AI Idea to Business Outcome

Imagine a retail company wants predictive analytics solutions for retail. The first request sounds simple: build a dashboard to forecast demand.

A code-first team may immediately start designing charts, connecting data sources, and building the interface.

A communication-first team asks different questions.

  • Who will use the forecast?
  • Which decision will it improve?
  • Is the data clean enough?
  • How often should the model update?
  • What happens when the forecast is wrong?
  • How will the business measure success?

After discovery, the team may realize the real problem is not the dashboard. The real problem is delayed inventory decisions across regions. The better solution may include clean data pipelines, demand forecasting, role-based alerts, and integration with existing planning tools.

This is how a dedicated software development team creates ROI. Not by writing more code, but by building the right system.

The same approach works for AI-powered automation for logistics, natural language processing services, custom AI agent development, progressive web app development, and digital transformation consulting.

This is also why many companies searching for the best IT outsourcing countries in Asia should not look only at cost. They should look for communication maturity, technical depth, process discipline, and business understanding.

Takeaway: The right partner does not just accept requirements. The right partner improves them.

The Inument Way

Inument’s approach is simple: communicate before building, validate before scaling, and connect every technical decision to business value.

When clients come to Inument for AI staff augmentation services, enterprise software development in Dhaka, React JS development agency support, custom SaaS application development, legacy system modernization services, or scalable cloud-native app development, the work does not begin with code.

It begins with questions.

  • What business problem are we solving?
  • Who will use this system?
  • What process is currently slow or expensive?
  • What metric should improve?
  • What should we avoid building?
  • What risks should we remove early?
  • How will success be measured after launch?

This is how Inument reduces conceptual bugs, prevents feature bloat, and helps engineering become a strategic function instead of only a production function.

For companies searching for Inument Solution Ltd reviews, the better question is not only, “Can this team build software?” The better question is, “Can this team understand our business and help us build the right software?”

That is where Inument aims to distinguish itself as an offshore AI development company and remote engineering partner.

Takeaway: The best engineering partners do not only provide developers. They help you make better technical decisions.

Conclusion: Build With Clarity, Not Just Speed

Great code still matters. Clean architecture matters. Strong developers matter. AI, cloud, SaaS, DevOps, mobile, and automation all matter.

But none of them matter enough if the team is solving the wrong problem.

A company can have a fast CI/CD pipeline, modern infrastructure, beautiful UI, and advanced AI models. But if the product does not improve the customer experience, reduce cost, increase revenue, or improve operations, the business still loses.

Communication is what keeps engineering on the right track.

  • It connects strategy with execution.
  • It connects product ideas with user needs.
  • It connects architecture with growth.
  • It connects AI ambition with operational reality.

Great code is the engine. Communication is the steering wheel.

At Inument, we help companies build technology that does not just launch. We help them build systems that perform, scale, and create measurable business value.

Whether you are building an AI product, modernising a legacy system, scaling a SaaS platform, strengthening a mobile app, or growing your engineering team, the rule for 2026 is clear:

Do not just build faster. Build with clarity. Build with purpose. Build for ROI.
About the Author

Safkat Nirjash

Safkat Nirjash

Want to Build Your Dream Tech Team? Hire Now!